Where the LUTs go
You will learn
Which part of a design spends the LUTs, and why hierarchy matters.
A design is built from modules that contain modules. When yosys keeps the hierarchy, it counts each submodule once, and the instance counts tell you how many copies there are. The treemap multiplies them out and shows which submodule eats the LUTs. One adder used many times can cost more than everything else together.
Try it
Switch between the hierarchical and flattened totals and find the largest tile. In the spec frame, find fpga_util and the test that turns 31700 used LUTs into a share of one chip: what percent does it get?
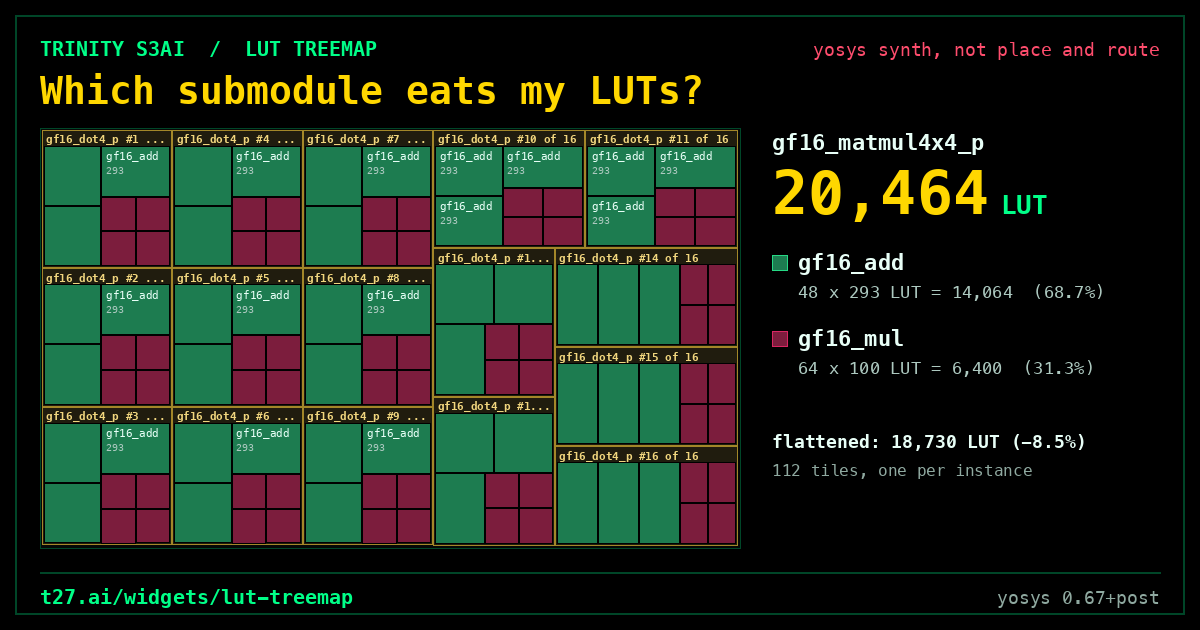
Drop yosys stat -json from a run without -flatten: a treemap of LUTs or FFs per submodule, each times its instance count, beside the flattened total. Read in your browser.
specs/fpga/partition.t27
// SPDX-License-Identifier: Apache-2.0
// t27/specs/fpga/partition.t27
// T27 Multi-FPGA Partition Specification
// Automatically partitions HIR modules across multiple FPGAs
// Estimates inter-FPGA bandwidth and latency
// Uses flat arrays + count fields (parser-compatible)
// phi^2 + 1/phi^2 = 3 | TRINITY

module Partition {

    // === FPGA node ===

    pub struct FpgaNode {
        name : &str,
        device : &str,
        luts : u32,
        ffs : u32,
        bram18 : u32,
        dsp48 : u32,
        io_pins : u32,
    }

    fn fpga_node(name: &str, device: &str, luts: u32, ffs: u32, bram18: u32, dsp48: u32, io: u32) -> FpgaNode {
        return FpgaNode{
            .name = name,
            .device = device,
            .luts = luts,
            .ffs = ffs,
            .bram18 = bram18,
            .dsp48 = dsp48,
            .io_pins = io,
        };
    }

    fn arty_a7_node(name: &str) -> FpgaNode {
        return fpga_node(name, "xc7a100t", 63400, 126800, 135, 240, 300);
    }

    // === Inter-FPGA link ===

    pub struct InterFpgaLink {
        fpga_a : u32,
        fpga_b : u32,
        width : u32,
        protocol : i8,
        max_mbps : u32,
    }

    fn lvds_link(a: u32, b: u32, width: u32) -> InterFpgaLink {
        return InterFpgaLink{
            .fpga_a = a,
            .fpga_b = b,
            .width = width,
            .protocol = 0,
            .max_mbps = 1000,
        };
    }

    fn serdes_link(a: u32, b: u32) -> InterFpgaLink {
        return InterFpgaLink{
            .fpga_a = a,
            .fpga_b = b,
            .width = 4,
            .protocol = 1,
            .max_mbps = 6250,
        };
    }

    fn link_bandwidth_mbps(link: InterFpgaLink) -> u32 {
        return link.width * link.max_mbps;
    }

    // === Partition assignment ===

    pub struct PartitionAssign {
        module_name : &str,
        fpga_idx : u32,
        luts : u32,
        ffs : u32,
        bram18 : u32,
        dsp48 : u32,
    }

    fn assignment(mod_name: &str, fpga: u32, luts: u32, ffs: u32, bram: u32, dsp: u32) -> PartitionAssign {
        return PartitionAssign{
            .module_name = mod_name,
            .fpga_idx = fpga,
            .luts = luts,
            .ffs = ffs,
            .bram18 = bram,
            .dsp48 = dsp,
        };
    }

    // === Partition result ===

    pub struct PartitionResult {
        num_fpgas : u32,
        num_assignments : u32,
        num_links : u32,
        total_bandwidth_mbps : u32,
        balanced : bool,
        errors : u32,
    }

    fn partition_ok(fpgas: u32, assigns: u32, links: u32, bw: u32) -> PartitionResult {
        return PartitionResult{
            .num_fpgas = fpgas,
            .num_assignments = assigns,
            .num_links = links,
            .total_bandwidth_mbps = bw,
            .balanced = true,
            .errors = 0,
        };
    }

    fn partition_fail(errors: u32) -> PartitionResult {
        return PartitionResult{
            .num_fpgas = 0,
            .num_assignments = 0,
            .num_links = 0,
            .total_bandwidth_mbps = 0,
            .balanced = false,
            .errors = errors,
        };
    }

    fn passed(r: PartitionResult) -> bool {
        return r.errors == 0;
    }

    // === Query ===

    fn total_link_bandwidth(links: [InterFpgaLink], count: u32) -> u32 {
        var total : u32 = 0;
        var i : u32 = 0;
        while i < count {
            total = total + link_bandwidth_mbps(links[i]);
            i = i + 1;
        }
        return total;
    }

    fn fpga_util(fpga: FpgaNode, used_luts: u32) -> u32 {
        if fpga.luts == 0 {
            return 0;
        }
        return used_luts * 100 / fpga.luts;
    }

    fn fpga_remaining(fpga: FpgaNode, used_luts: u32) -> u32 {
        if used_luts > fpga.luts {
            return 0;
        }
        return fpga.luts - used_luts;
    }

    // === Validation ===

    fn validate_node(n: FpgaNode) -> u32 {
        var errors : u32 = 0;
        if n.name == "" {
            errors = errors + 1;
        }
        if n.luts == 0 {
            errors = errors + 1;
        }
        return errors;
    }

    // === Tests ===

    test fpga_node_creation
        given n = arty_a7_node("fpga0")
        then n.name == "fpga0"
        and n.device == "xc7a100t"
        and n.luts == 63400

    test fpga_node_direct
        given n = fpga_node("test_fpga", "xc7k325t", 203600, 407200, 445, 840, 500)
        then n.name == "test_fpga"
        and n.device == "xc7k325t"
        and n.luts == 203600
        and n.ffs == 407200
        and n.bram18 == 445
        and n.dsp48 == 840
        and n.io_pins == 500

    test lvds_link_creation
        given l = lvds_link(0, 1, 8)
        then l.fpga_a == 0
        and l.fpga_b == 1
        and l.width == 8
        and link_bandwidth_mbps(l) == 8000

    test serdes_link_creation
        given l = serdes_link(0, 1)
        then l.protocol == 1
        and link_bandwidth_mbps(l) == 25000

    test assignment_creation
        given a = assignment("uart", 0, 200, 100, 1, 0)
        then a.module_name == "uart"
        and a.fpga_idx == 0

    test partition_ok_creation
        given r = partition_ok(2, 5, 1, 8000)
        then r.num_fpgas == 2
        and r.balanced == true
        and passed(r) == true

    test partition_fail_creation
        given r = partition_fail(1)
        then passed(r) == false

    test total_link_bandwidth
        given l1 = lvds_link(0, 1, 8)
        and l2 = lvds_link(1, 2, 4)
        then total_link_bandwidth([l1, l2], 2) == 12000

    test fpga_util_calc
        given n = arty_a7_node("fpga0")
        then fpga_util(n, 31700) == 50

    test fpga_remaining_calc
        given n = arty_a7_node("fpga0")
        then fpga_remaining(n, 10000) == 53400

    test fpga_remaining_over
        given n = arty_a7_node("fpga0")
        then fpga_remaining(n, 100000) == 0

    test validate_node_ok
        given n = arty_a7_node("fpga0")
        then validate_node(n) == 0

    test validate_node_empty
        given n = FpgaNode{.name = "", .device = "xc7a100t", .luts = 0, .ffs = 0, .bram18 = 0, .dsp48 = 0, .io_pins = 0}
        then validate_node(n) > 0

    // === Invariants ===

    invariant bandwidth_non_negative
        given l = lvds_link(0, 1, 8)
        assert link_bandwidth_mbps(l) >= 0

    invariant util_bounded
        given n = arty_a7_node("inv")
        assert fpga_util(n, 0) == 0

    bench fpga_util_latency
        measure: nanoseconds to fpga_util(arty_a7_node("bench"), 15850)
        target: < 50ns

    bench link_bandwidth_latency
        measure: nanoseconds to link_bandwidth_mbps(lvds_link(0, 1, 8))
        target: < 50ns
}

// phi^2 + 1/phi^2 = 3 | TRINITY
All lessons
Module 1 · The chip
What an FPGA is, which chip we use, and how its pins meet the board.
Module 2 · Numbers in hardware
Bits, trits and number formats, and what arithmetic costs in logic.
Module 3 · Your t27 program
Write a spec, test it, and see why compiling is not the same as being right.
Module 4 · Inside t27c
How the compiler reads a spec and what it writes, including the native t27b.
Module 5 · From spec to hardware
The Verilog t27c writes, the cells it becomes, and what one LUT does.
Module 6 · Reading synthesis
What yosys reports about your design, and which warnings matter.
Module 7 · Place, route, timing
Where the cells land on the die, and whether the clock is met.
Module 8 · The bitstream
How a routed design becomes the bits the chip loads, with no Vivado.
Module 9 · On the board
Ask the chip who it is, load the bits, and check them.