T27: a number format of our own
You will learn
How three trits give more levels than a 4-bit float, and what that costs in plain bits.
A 4-bit float such as E2M1, the element of NVFP4 and MXFP4, has 16 codes, and two of them are zero. Three balanced trits have 3 x 3 x 3 = 27 states. T27 is our format that uses all of them: 27 levels placed where a trained network's weights actually fall, and one shared scale per block of weights. On ternary storage that is more levels in the same room. Packed into plain binary bits it is larger, not smaller, and the widget shows both counts.
Try it
Move the weight across the range and find where E2M1 rounds worse than T27; then read the storage table in bits. In the spec frame, tnf8 spends three trits on a float exponent: find the test that counts its values, and the offset it reserves.
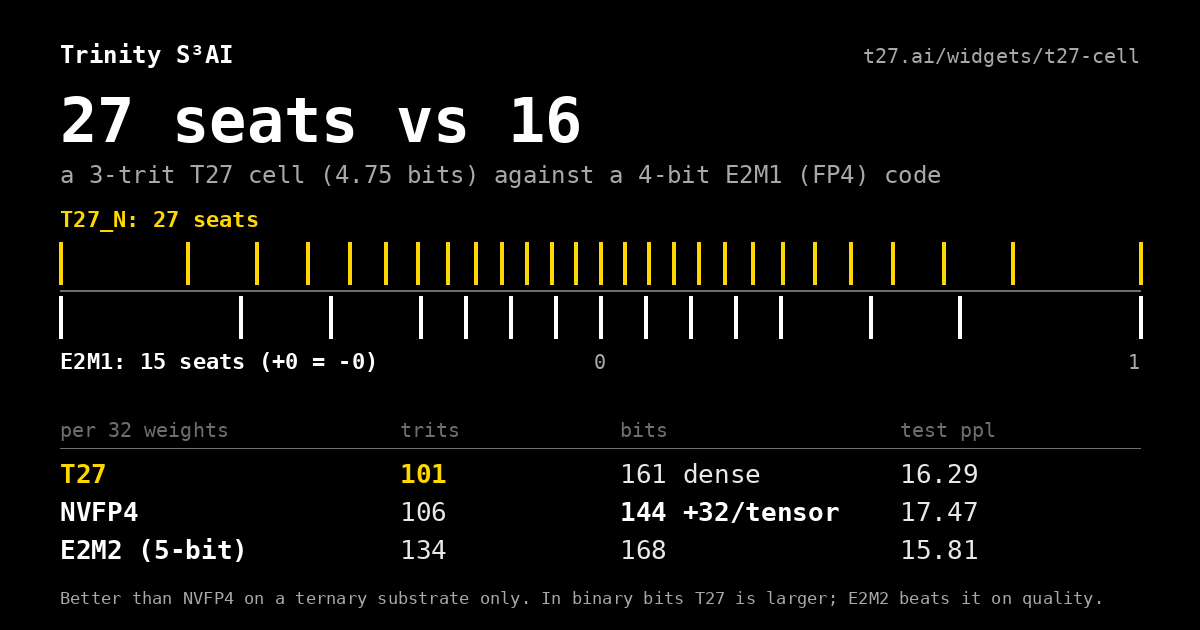
Drag a weight along one line and see where a 27-level T27 cell and a 4-bit E2M1 code round it, and what 32 weights cost in trits and in bits. Numbers from two compiled .t27 specs.
specs/numeric/tnf8.t27
// SPDX-License-Identifier: Apache-2.0
// tnf8.t27 -- TNF8: Ternary Network Float, 8-bit class.
// Rung of the TF ladder (TF4/8/16/32). Balanced-ternary exponent = 3 trits
// (3^3 = 27 offsets, exponent +-13, ~8 decades), phi-ish 4-bit mantissa, NO
// regime decode. Beats tekum-8 by the same structural argument as TF16 beats
// tekum16: fixed fields + native balanced-ternary exponent add, uniform mantissa.
//   layout: [ sign(1) | E = 3 balanced-ternary trits | M = 4 bits ]
// phi^2 + 1/phi^2 = 3 | TRINITY

module triformat_tnf8 {
    use base::types;

    const EXP_TRITS: u32 = 3;
    const MANT_BITS: u32 = 4;
    const EXP_OFFSET: u32 = 13;    // (3^3 - 1) / 2
    const OFFSET_MAX: u32 = 26;    // 3^3 - 1 (reserved special row)

    // 3-trit exponent field -> unsigned offset in [0,26].
    fn exp_offset(t0: u32, t1: u32, t2: u32) -> u32 {
        return t0 + (3 * t1) + (9 * t2);
    }

    fn is_finite(offset: u32) -> bool {
        return offset != OFFSET_MAX;
    }

    fn exp_values() -> u32 {
        return 27;
    }

    // ---- Tests / invariants ----
    test offset_range {
        assert(exp_offset(0, 0, 0) == 0, "min offset (exponent -13)");
        assert(exp_offset(2, 2, 2) == 26, "max offset (reserved special)");
        assert(exp_offset(1, 1, 1) == 13, "center offset = exponent 0 (unity)");
    }
    test finiteness {
        assert(is_finite(13) == true, "unity finite");
        assert(is_finite(26) == false, "offset 26 special");
        assert(exp_values() == 27, "3^3 exponent values (~8 decades) in 3 trits");
    }
}
All lessons
Module 1 · Lab: our own research
A number format of our own, an honest scoreboard, and a model's tables multiplied on the board.
Module 2 · AI numbers: the MX block
How AI chips keep weights in a few bits: one shared scale per block, the scale byte itself, and what one outlier does to its neighbours.
Module 3 · Ternary weights
Weights that are only minus, zero or plus a scale, the five rules a ternary alphabet must pass, and a test pass that checked nothing.
Module 4 · The Ternary Network Float
A rule the compiler enforces before any test runs, and a 17-bit float whose exponent is four balanced trits.
Module 5 · Arithmetic on signed numbers
Multiply two signed numbers, add them when their signs differ, and do both at once in a multiply-accumulate.
Module 6 · Parts of a neuron
A ReLU that bends at zero, a power of two for softmax, and an argmax that names the answer.
Module 7 · Learning from a mistake
A loss that prices a wrong guess in bits, one step that moves a weight against its gradient, and the hidden layer that XOR needs.
Module 8 · BitNet: ternary networks
A threshold that squeezes a sum back to three values, one neuron that becomes a different function when its weights change, and a neuron that reads its inputs 27 trits at a time.
Module 9 · The ternary MAC as a chip
The 27-trit dot product as wires with no register, the same sum added into a register on every clock, and a small whole network to close the course.