An honest scoreboard
You will learn
How T27 was compared with NVFP4, MX+ and MXFP4 on a real language model, and what the result does not show.
A format is judged by what it does to a model. We stored the weights of one small language model in each format and measured perplexity on text it had not seen: lower is better. The rule was written before the run: T27 beats a rival when its perplexity is below 990 thousandths of the rival's. It beat NVFP4, MX+ and MXFP4, and it lost to E2M2, a wider format. The panel under the bars lists what this test cannot claim. The one claim that holds: T27 beats NVFP4 on a ternary substrate.
Try it
Find the NVFP4 ratio and the threshold line; then name the format T27 loses to and what it pays for that. The spec frame is a control for another claim: find what its header says a posit match would falsify, and the test that holds es at 2 for every width.
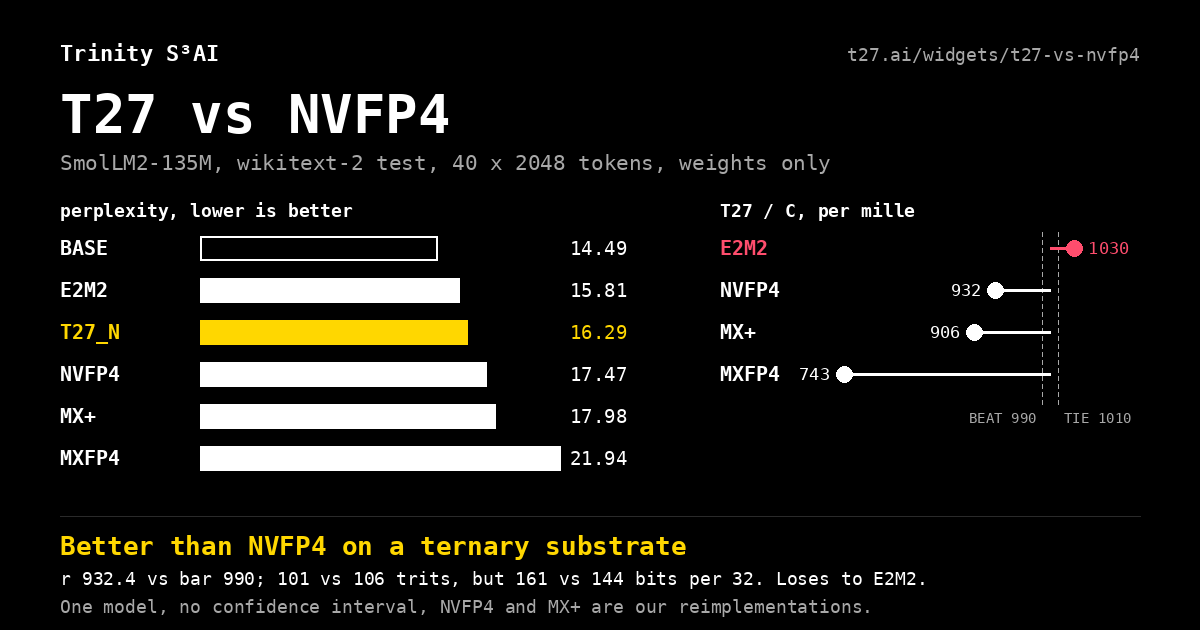
Perplexity of six weight formats on SmolLM2-135M and the pre-registered ladder: T27 better than NVFP4, MX+ and MXFP4 on a trit substrate, worse than E2M2. Every limit listed.
specs/numeric/posit_ladder_control.t27
// SPDX-License-Identifier: Apache-2.0
// t27/specs/numeric/posit_ladder_control.t27
// Posit ladder -- the F3 CONTROL for the GoldenFloat breadth-as-moat bet (FL-004)
// NUMERIC-STANDARD-003
//
// PURPOSE (goldenfloat-ladder skill, F3 leg):
//   The breadth-as-moat claim (FL-004) is that ONE closed rule across a width
//   ladder gives a defensible toolchain-coherence advantage. Posit is the
//   strongest published precedent for "one parameterised rule across widths",
//   so it is the natural CONTROL. This spec encodes the posit field model so a
//   later head-to-head (F2/F3) compares against a faithful, sourced control --
//   NOT a strawman. If a posit ladder matches the phi-ladder on breadth
//   (lossy-conversion count) AND per-rung accuracy at matched bit budgets, the
//   moat (FL-004) is FALSIFIED and demoted to [Risk] -- recorded FIRST.
//
// HONESTY / SOURCING (claim-status discipline):
//   There are TWO published posit exponent-size (es) schedules. Both are encoded
//   so neither can be quietly strawmanned:
//     (A) PRE-STANDARD draft (Gustafson/Yonemoto 2017; de Dinechin et al. 2019):
//         es grows with width -- posit8 es=0, posit16 es=1, posit32 es=2,
//         posit64 es=3, posit128 es=4. Source: de Dinechin et al. 2019
//         "Posits: the good, the bad and the ugly".
//     (B) RATIFIED 2022 Posit Standard: es = 2 FIXED for ALL widths.
//         Source: Posit Standard (2022), posithub.org/docs/posit_standard-2.pdf .
//   This file makes NO claim that the phi-ladder is better than either posit
//   schedule -- that is [Open conjecture] decided by measurement, not by spec.
//
// KEY POSIT FACTS (unlike a fixed-field float, posit fields are DATA-DEPENDENT):
//   A posit has sign(1) + regime(variable, run-length) + exponent(<= es) +
//   fraction(remaining). So there is NO fixed exponent:mantissa split per width
//   the way GoldenFloat has e=round((N-1)/phi^2). That structural difference is
//   the honest contrast: GF fixes the split by a closed rule; posit tapers it
//   per value. Neither is "better" a priori -- F2/F3 must measure it.
//
// L5 IDENTITY: this control file still carries the [Verified] phi-anchor so the
//   conformance/identity gate holds repo-wide; it is NOT a phi claim about posit.

module PositLadderControl {
    use base::types;

    const PHI     : f64 = 1.6180339887498948482;
    const TRINITY : f64 = 3.0;          // L_2, the only [Verified] phi-fact here
    const TOL_F64 : f64 = 1.0e-9;

    fn abs_f64(x: f64) f64 {
        if (x < 0.0) { return -x; }
        return x;
    }

    // useed = 2^(2^es). The posit regime scales by powers of useed.
    fn useed(es: u32) f64 {
        return pow(2.0, pow(2.0, es as f64));
    }

    // Pre-standard (schedule A) es as a function of total width n.
    // posit8->0, posit16->1, posit32->2, posit64->3, posit128->4.
    // Derived rule for these widths: es = log2(n) - 3.
    fn es_prestandard(n: u32) u32 {
        if (n == 8)   { return 0; }
        if (n == 16)  { return 1; }
        if (n == 32)  { return 2; }
        if (n == 64)  { return 3; }
        if (n == 128) { return 4; }
        return 2;  // default to standard es for unlisted widths
    }

    // Ratified 2022 standard (schedule B): es = 2 for every width.
    fn es_standard(n: u32) u32 {
        return 2;
    }

    // Max fraction bits available at the BEST case (regime minimal = 2 bits:
    // one regime bit + one terminating bit). f_max = n - 1(sign) - 2(regime) - es.
    // This is the most-fraction case; posit tapers DOWN from here as |x| departs 1.
    fn frac_bits_best(n: u32, es: u32) i64 {
        return (n as i64) - 1 - 2 - (es as i64);
    }

    // ---- L5 identity anchor (repo-wide gate; not a posit claim) ----

    invariant posit_ctrl_phi_square_identity
        assert abs_f64(PHI * PHI - (PHI + 1.0)) < TOL_F64

    invariant posit_ctrl_trinity_is_three
        assert abs_f64(PHI * PHI + (1.0 / (PHI * PHI)) - TRINITY) < TOL_F64

    // ---- Pre-standard es schedule (A) -- sourced, exact ----

    test posit_prestandard_es_schedule
        var ok = true
        if (es_prestandard(8)   != 0) { ok = false; }
        if (es_prestandard(16)  != 1) { ok = false; }
        if (es_prestandard(32)  != 2) { ok = false; }
        if (es_prestandard(64)  != 3) { ok = false; }
        if (es_prestandard(128) != 4) { ok = false; }
        then ok == true

    test posit_useed_grows_with_es
        // useed(0)=2, useed(1)=4, useed(2)=16, useed(3)=256
        var ok = true
        if (abs_f64(useed(0) - 2.0)   >= TOL_F64) { ok = false; }
        if (abs_f64(useed(1) - 4.0)   >= TOL_F64) { ok = false; }
        if (abs_f64(useed(2) - 16.0)  >= TOL_F64) { ok = false; }
        if (abs_f64(useed(3) - 256.0) >= TOL_F64) { ok = false; }
        then ok == true

    // ---- Ratified 2022 standard es schedule (B) -- fixed es=2 ----

    test posit_standard_es_is_two_for_all_widths
        var ok = true
        var n : u32 = 8
        while (n <= 256) {
            if (es_standard(n) != 2) { ok = false; }
            n = n * 2;
        }
        then ok == true

    // ---- Structural contrast vs GoldenFloat (the honest F3 framing) ----

    test posit_best_case_fraction_is_width_dependent
        // posit32, standard es=2: best-case fraction = 32 - 1 - 2 - 2 = 27 bits.
        // (GoldenFloat GF32 fixes mantissa at 19 bits by e=round(31/phi^2)=12.)
        // The point is NOT 27 > 19 -- posit TAPERS down from 27 as |x| leaves 1,
        // while GF holds 19 constant. Breadth/coherence, not per-rung accuracy,
        // is what FL-004 must measure.
        given f = frac_bits_best(32, 2)
        then f == 27

    test posit_taper_means_no_fixed_split
        // A control assertion documenting the structural difference: posit's
        // exponent+fraction split is data-dependent (regime is run-length), so
        // there is no single (e, m) pair per width as GoldenFloat defines.
        given f64_bits = frac_bits_best(64, 3)   // 64 - 1 - 2 - 3 = 58 best case
        then f64_bits == 58

    bench posit_useed_latency
        given es = 3
        when  _ = useed(es)
        then elapsed_time_ns < 200
}
All lessons
Module 1 · Lab: our own research
A number format of our own, an honest scoreboard, and a model's tables multiplied on the board.
Module 2 · AI numbers: the MX block
How AI chips keep weights in a few bits: one shared scale per block, the scale byte itself, and what one outlier does to its neighbours.
Module 3 · Ternary weights
Weights that are only minus, zero or plus a scale, the five rules a ternary alphabet must pass, and a test pass that checked nothing.
Module 4 · The Ternary Network Float
A rule the compiler enforces before any test runs, and a 17-bit float whose exponent is four balanced trits.
Module 5 · Arithmetic on signed numbers
Multiply two signed numbers, add them when their signs differ, and do both at once in a multiply-accumulate.
Module 6 · Parts of a neuron
A ReLU that bends at zero, a power of two for softmax, and an argmax that names the answer.
Module 7 · Learning from a mistake
A loss that prices a wrong guess in bits, one step that moves a weight against its gradient, and the hidden layer that XOR needs.
Module 8 · BitNet: ternary networks
A threshold that squeezes a sum back to three values, one neuron that becomes a different function when its weights change, and a neuron that reads its inputs 27 trits at a time.
Module 9 · The ternary MAC as a chip
The 27-trit dot product as wires with no register, the same sum added into a register on every clock, and a small whole network to close the course.