A whole network
You will learn
How the pieces of this course fit into one small network, and what its tests and its Verilog still leave open.
mlp2 in bitnet_mlp.t27 is a whole network: 3 neurons read the input, pack3 packs their 3 trits into a hidden chunk, and 2 neurons turn it into 2 output trits. The course went from number formats and arithmetic to a neuron, training, ternary weights and the chip; here are the neuron, the weights and an on_comb entry, and no training. The native t27c runs all 4 tests, all pass, none vacuous; the browser skips them, and none calls mlp2. The generated Verilog marks the chunk loop in neuronN NOT UNROLLED, and its note says yosys rejects it, so it is not yet a chip. The recording moves the third hidden trit from bit 4 to bit 3 on line 39, and exactly one test fails, pack3_zzz. Every byte in the recording was printed by the command; only the typing is staged.
Try it
In the recording, find the pack3 line before and after the change; then in the spec frame open Code, pick verilog and find the loop in neuronN marked NOT UNROLLED.
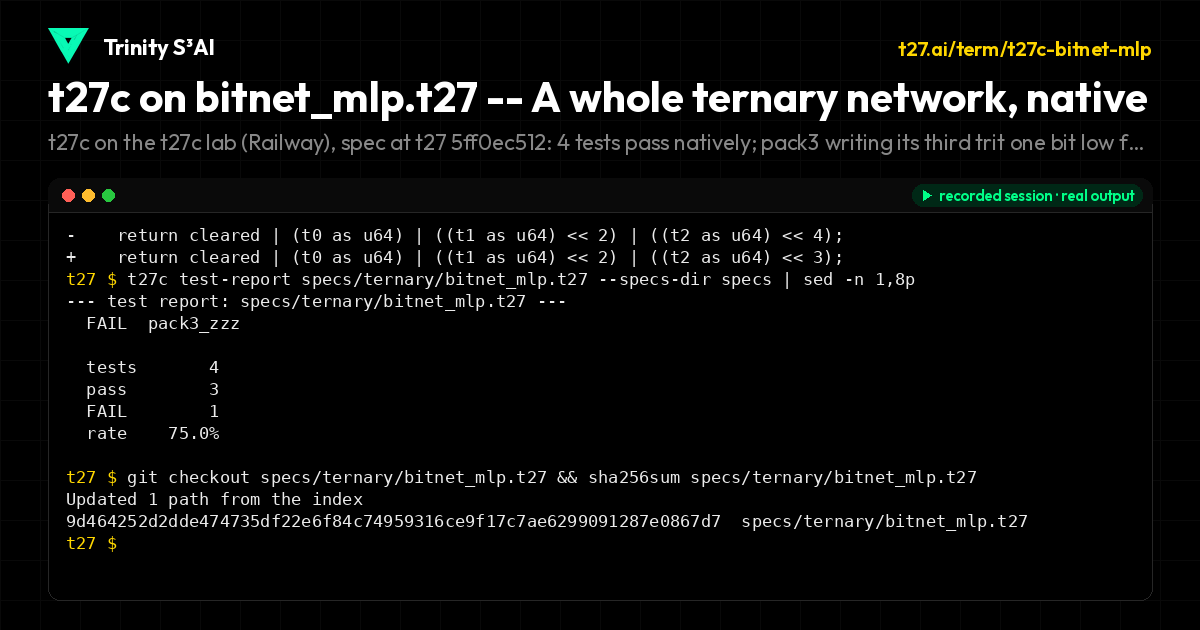
t27c on the t27c lab (Railway), spec at t27 5ff0ec512: 4 tests pass natively; pack3 writing its third trit one bit low fails exactly one test, pack3_zzz; git restores the spec.
specs/ternary/bitnet_mlp.t27
module BitnetMlp;
fn tmul(ta: u8, tb: u8) -> i8 {
    if (ta == 1) { return 0; }
    if (tb == 1) { return 0; }
    if (ta == tb) { return 1; }
    return -1;
}
fn dot27(a: u64, b: u64) -> i16 {
    var acc : i16 = 0;
    var i : u32 = 0;
    while (i < 27) {
        var ta : u8 = ((a >> (i << 1)) & 3) as u8;
        var tb : u8 = ((b >> (i << 1)) & 3) as u8;
        acc = acc + tmul(ta, tb) as i16;
        i = i + 1;
    }
    return acc;
}
fn quantize(v: i16, threshold: i16) -> u8 {
    if (v > threshold) { return 2; }
    if (v < -threshold) { return 0; }
    return 1;
}
fn neuronN(acts: [8]u64, weights: [8]u64, nchunks: u32, threshold: i16) -> u8 {
    var acc : i16 = 0;
    var c : u32 = 0;
    while (c < nchunks) {
        acc = acc + dot27(acts[c], weights[c]);
        c = c + 1;
    }
    return quantize(acc, threshold);
}
fn neuron1(act: u64, weight: u64, threshold: i16) -> u8 {
    return quantize(dot27(act, weight), threshold);
}
fn pack3(t0: u8, t1: u8, t2: u8) -> u64 {
    var z : u64 = 6004799503160661;
    var cleared : u64 = z & 18446744073709551552;
    return cleared | (t0 as u64) | ((t1 as u64) << 2) | ((t2 as u64) << 4);
}
// 2-layer BitNet inference. Layer 1: 3 neurons over the input activations
// (l1chunks chunks) -> 3 trits packed into one hidden chunk. Layer 2: 2
// single-chunk neurons over that hidden chunk -> 2 packed output trits.
pub fn mlp2(acts: [8]u64, wa0: [8]u64, wa1: [8]u64, wa2: [8]u64, wb0: u64, wb1: u64, l1chunks: u32, threshold: i16) -> u8 {
    var t0 : u8 = neuronN(acts, wa0, l1chunks, threshold);
    var t1 : u8 = neuronN(acts, wa1, l1chunks, threshold);
    var t2 : u8 = neuronN(acts, wa2, l1chunks, threshold);
    var h : u64 = pack3(t0, t1, t2);
    var o0 : u8 = neuron1(h, wb0, threshold);
    var o1 : u8 = neuron1(h, wb1, threshold);
    return (o1 << 2) | o0;
}
test dot27_all_n { assert_eq(dot27(0, 0), 27); }
test neuron1_p_p { assert_eq(neuron1(12009599006321322, 12009599006321322, 10), 2); }
test pack3_zzz { assert_eq(pack3(1, 1, 1), 6004799503160661); }
test quantize_band { assert_eq(quantize(5, 10), 1); }
// W699: the hardware boundary, with a width the EMITTER can produce.
//
// W698 accepted `[8]u64` while the port emitter still sized entry ports with
// `type_to_width`, whose last arm is `_ => 32`. This parameter became
// `input wire [31:0]` -- a silent 16x narrowing, and the banner, the census,
// the corpus column and yosys all reported success. It was retracted the same
// wave.
//
// W699 replaced that call with `entry_port_width`, which returns None rather
// than a plausible number and makes the entry point refuse LOUDLY in the
// generated source. Verified end to end: this parameter now emits
// `input wire [511:0]`, and `on_comb` and the function it forwards to both
// take [511:0], so nothing is truncated between the boundary and the body.
fn on_comb(acts: [8]u64, wa0: [8]u64, wa1: [8]u64, wa2: [8]u64, wb0: u64, wb1: u64, l1chunks: u32, threshold: i16) -> u8 { return mlp2(acts, wa0, wa1, wa2, wb0, wb1, l1chunks, threshold); }

endmodule
All lessons
Module 1 · Lab: our own research
A number format of our own, an honest scoreboard, and a model's tables multiplied on the board.
Module 2 · AI numbers: the MX block
How AI chips keep weights in a few bits: one shared scale per block, the scale byte itself, and what one outlier does to its neighbours.
Module 3 · Ternary weights
Weights that are only minus, zero or plus a scale, the five rules a ternary alphabet must pass, and a test pass that checked nothing.
Module 4 · The Ternary Network Float
A rule the compiler enforces before any test runs, and a 17-bit float whose exponent is four balanced trits.
Module 5 · Arithmetic on signed numbers
Multiply two signed numbers, add them when their signs differ, and do both at once in a multiply-accumulate.
Module 6 · Parts of a neuron
A ReLU that bends at zero, a power of two for softmax, and an argmax that names the answer.
Module 7 · Learning from a mistake
A loss that prices a wrong guess in bits, one step that moves a weight against its gradient, and the hidden layer that XOR needs.
Module 8 · BitNet: ternary networks
A threshold that squeezes a sum back to three values, one neuron that becomes a different function when its weights change, and a neuron that reads its inputs 27 trits at a time.
Module 9 · The ternary MAC as a chip
The 27-trit dot product as wires with no register, the same sum added into a register on every clock, and a small whole network to close the course.