Сдвиг и сложение
Вы узнаете
Почему умножитель — это стопка сдвинутых частичных произведений и сколько их стоит число.
Каждый бит множителя, равный 1, добавляет копию множимого, сдвинутую на позицию этого бита; каждый бит 0 не добавляет ничего. 200 x 13 — это 200 + 800 + 1600 = 2600, три строки из восьми. Два 8-битных числа дают не больше чем 16-битное произведение, а матричный умножитель — ровно эта сетка вентилей AND, питающая деревья сохранения переноса из прошлого урока. Спека multipliers.t27 вычисляет каждую строку и текущую сумму, которые рисует виджет.
Попробовать
Пройдите 200 x 13 строка за строкой; затем найдите множитель b от 0 до 255, при котором складываются все восемь строк, и такой, при котором складывается одна.
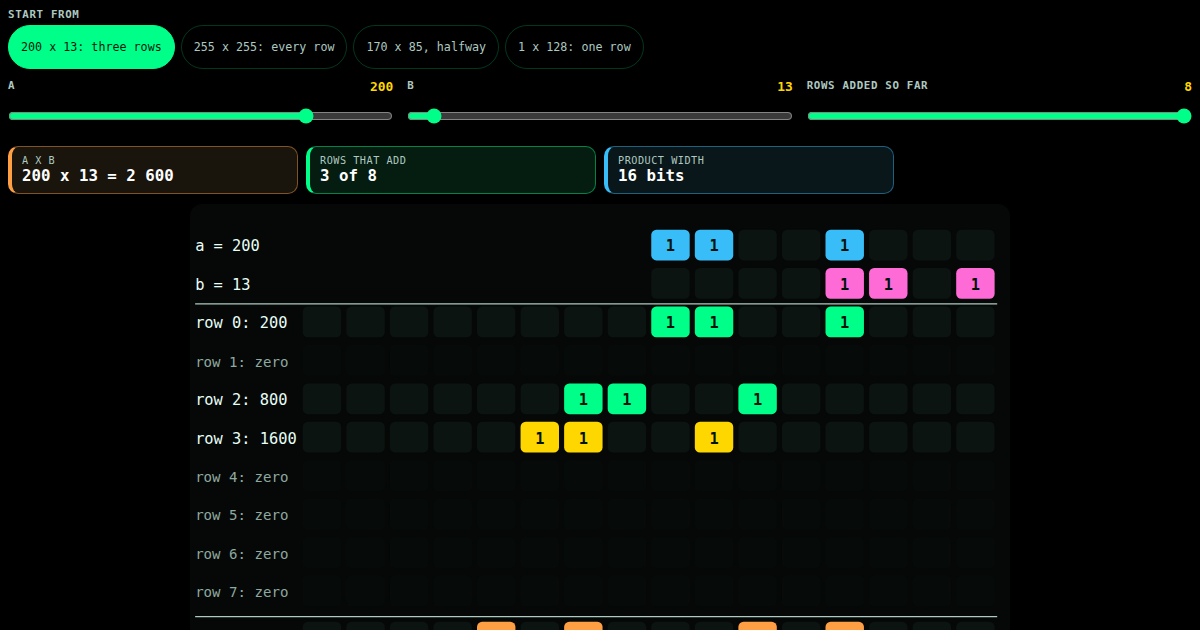
Pick two 8-bit numbers and step through the partial products: one shifted copy of a for each 1 bit of b, summed row by row into the product.
specs/fpga/dsp/multipliers.t27
// SPDX-License-Identifier: Apache-2.0
// specs/fpga/dsp/multipliers.t27 -- multiplying in hardware: shift and add, radix-4 Booth, the DSP48E1 slice
// Host: gHashTag/trinity apps/website public/widgets/{shift-add,booth-radix4,dsp-fit}/ (module 2 of
//       the course arithmetic-and-dsp): each widget's logic.js is these fn bodies compiled to wasm
//       (scripts/t27-logic.mjs in gHashTag/999-multibots-telegraf, types stripped); the pages
//       write no formula of their own.
//
// SHIFT AND ADD. a * b is the sum, over the bits of b that are 1, of a shifted left by that
// bit's position: one partial product per bit of the multiplier.
//
// RADIX-4 BOOTH (A. D. Booth, "A signed binary multiplication technique", Q. J. Mech. Appl. Math.
// 4(2), 1951; the radix-4 form by O. L. MacSorley, Proc. IRE 49, 1961). Read the two's
// complement multiplier b in overlapping groups (b(2k+1), b(2k), b(2k-1)), b(-1) = 0, and map
// each group to a digit in {-2, -1, 0, +1, +2}: 000 0, 001 +1, 010 +1, 011 +2, 100 -2, 101 -1,
// 110 -1, 111 0 -- that is digit = -2 b(2k+1) + b(2k) + b(2k-1). Then a * b = sum_k digit_k *
// a * 4^k over w/2 digits: half the partial products of shift and add, each one a shift and
// maybe a negation of a. Example: 3 * 6 (w = 8): digits, low first, -2, +2, 0, 0 -> 18.
//
// THE DSP48E1 SLICE (Xilinx UG479, "7 Series DSP48E1 Slice User Guide"; DS180 counts 740 of
// them on the XC7A200T): a 25 x 18 two's complement multiplier into a 48-bit accumulator. A
// wider product is tiled: the low pieces of a split operand are unsigned and so carry one bit
// less than the port, which gives pieces(w, port) = 1 + ceil((w - port) / (port - 1)) for
// w > port, and the slice count is the cheaper of the two ways to put a and b on the 25 and 18
// ports. A w_a x w_b product needs w_a + w_b bits; summing `count` of them adds
// ceil(log2(count)) guard bits; it fits the accumulator while that total is at most 48.
//
// WHAT IT DOES NOT CLAIM: the tiling is a count model, not any synthesis tool's mapper (which
// may use LUTs for small pieces, or the pre-adder); timing is not modelled.
// Claim status: checked by the tests below -- Booth digits and products for 3 x 6, -7 x 5,
// 1234 x -5678 and the 16-bit corners against the products, 25 x 18 in one slice, 32 x 32 in 4,
// the 48-bit headroom of 25 x 18 (5 guard bits, 32 terms).
// phi^2 + 1/phi^2 = 3 | TRINITY

module fpga::dsp::multipliers {

    pub const KIND : str = "widget-logic";
    pub const ID : str = "multipliers";
    pub const VERSION : u8 = 1;
    pub const DSP_A_BITS : u8 = 25;
    pub const DSP_B_BITS : u8 = 18;
    pub const DSP_ACC_BITS : u8 = 48;
    pub const DSP48_ON_200T : u16 = 740;

    // ---- Shift and add ---------------------------------------------------------------------

    // Partial product i: a shifted left by i where bit i of b is 1, else 0.
    fn partial(a: u16, b: u16, i: u8) -> u32 {
        if (((b >> i) & 1) == 1) {
            return (a as u32) << i;
        }
        return 0;
    }

    // The sum of partial products 0..upto-1: the running total after `upto` rows.
    fn shift_add(a: u16, b: u16, upto: u8) -> u32 {
        var s : u32 = 0;
        var i : u8 = 0;
        while (i < upto && i < 16) {
            s = s + partial(a, b, i);
            i = i + 1;
        }
        return s;
    }

    // Rows that are not zero: one per 1 bit of the multiplier.
    fn rows_used(b: u16, w: u8) -> u8 {
        var n : u8 = 0;
        var i : u8 = 0;
        while (i < w) {
            n = n + ((b >> i) & 1) as u8;
            i = i + 1;
        }
        return n;
    }

    // ---- Radix-4 Booth ---------------------------------------------------------------------

    // Digit k of the multiplier b (two's complement): -2 b(2k+1) + b(2k) + b(2k-1).
    fn booth_digit(b: i32, k: u8) -> i8 {
        const hi = (b >> (2 * k + 1)) & 1;
        const mid = (b >> (2 * k)) & 1;
        var lo : i32 = 0;
        if (k > 0) {
            lo = (b >> (2 * k - 1)) & 1;
        }
        return (mid + lo - 2 * hi) as i8;
    }

    // Partial product k: digit_k * a * 4^k.
    fn booth_partial(a: i32, b: i32, k: u8) -> i32 {
        return (booth_digit(b, k) as i32) * a * ((1 as i32) << (2 * k));
    }

    // a * b for w-bit operands (w even, at most 16): the sum of w/2 Booth partial products.
    fn booth_product(a: i32, b: i32, w: u8) -> i32 {
        var s : i32 = 0;
        var k : u8 = 0;
        while (k < w / 2) {
            s = s + booth_partial(a, b, k);
            k = k + 1;
        }
        return s;
    }

    // Booth digits that are not zero: the partial products that cost an adder input.
    fn booth_nonzero(b: i32, w: u8) -> u8 {
        var n : u8 = 0;
        var k : u8 = 0;
        while (k < w / 2) {
            if (booth_digit(b, k) != 0) {
                n = n + 1;
            }
            k = k + 1;
        }
        return n;
    }

    // ---- The DSP48E1 slice -----------------------------------------------------------------

    // Pieces a w-bit signed operand splits into on a signed port of `port` bits.
    fn pieces(w: u8, port: u8) -> u8 {
        if (w <= port) {
            return 1;
        }
        return 1 + (w - port + port - 2) / (port - 1);
    }

    // The port operand a goes on in the cheaper tiling: DSP_A_BITS (25) unless the 18-bit
    // port takes fewer slices.
    fn a_port(wa: u8, wb: u8) -> u8 {
        const on_a = (pieces(wa, DSP_A_BITS) as u16) * (pieces(wb, DSP_B_BITS) as u16);
        const on_b = (pieces(wa, DSP_B_BITS) as u16) * (pieces(wb, DSP_A_BITS) as u16);
        if (on_b < on_a) {
            return DSP_B_BITS;
        }
        return DSP_A_BITS;
    }

    // Bits in piece j (0 = the lowest) of a w-bit operand on a port of `port` bits: the low
    // pieces carry port - 1 unsigned bits, the top one what is left with the sign; 0 past the top.
    fn piece_bits(w: u8, port: u8, j: u8) -> u8 {
        const count = pieces(w, port);
        if (j >= count) {
            return 0;
        }
        if (count == 1) {
            return w;
        }
        if (j + 1 < count) {
            return port - 1;
        }
        return w - (count - 1) * (port - 1);
    }

    // How many such multipliers the 740 slices of the XC7A200T hold.
    fn mults_on_200t(wa: u8, wb: u8) -> u16 {
        return DSP48_ON_200T / dsp_slices(wa, wb);
    }

    // Slices a w_a x w_b product takes: a on a_port(), b on the other port.
    fn dsp_slices(wa: u8, wb: u8) -> u16 {
        const pa = a_port(wa, wb);
        var pb : u8 = DSP_B_BITS;
        if (pa == DSP_B_BITS) {
            pb = DSP_A_BITS;
        }
        return (pieces(wa, pa) as u16) * (pieces(wb, pb) as u16);
    }

    // Guard bits to sum `count` products without overflow: ceil(log2(count)).
    fn guard_bits(count: u32) -> u8 {
        var g : u8 = 0;
        var cap : u32 = 1;
        while (cap < count && g < 32) {
            cap = cap * 2;
            g = g + 1;
        }
        return g;
    }

    // Accumulator bits left over above one w_a x w_b product (negative: it does not fit).
    fn headroom(wa: u8, wb: u8) -> i16 {
        return (DSP_ACC_BITS as i16) - (wa as i16) - (wb as i16);
    }

    // True when `count` products of w_a x w_b bits sum inside the 48-bit accumulator.
    fn acc_fits(wa: u8, wb: u8, count: u32) -> bool {
        return (wa as i16) + (wb as i16) + (guard_bits(count) as i16) <= (DSP_ACC_BITS as i16);
    }

    // The most products the accumulator can sum: 2^headroom, or 0 when one does not fit.
    fn max_terms(wa: u8, wb: u8) -> f64 {
        const h = headroom(wa, wb);
        if (h < 0) {
            return 0.0;
        }
        var t : f64 = 1.0;
        var i : i16 = 0;
        while (i < h) {
            t = t * 2.0;
            i = i + 1;
        }
        return t;
    }

    // Every a, b in -128..127: Booth on 8 bits gives the product.
    fn booth_is_exact_8() -> bool {
        var a : i32 = -128;
        while (a < 128) {
            var b : i32 = -128;
            while (b < 128) {
                if (booth_product(a, b, 8) != a * b) {
                    return false;
                }
                b = b + 1;
            }
            a = a + 1;
        }
        return true;
    }

    // ---- Tests -----------------------------------------------------------------------------

    test "shift and add is a sum of shifted copies" {
        assert(partial(200, 13, 0) == 200);
        assert(partial(200, 13, 1) == 0);
        assert(partial(200, 13, 3) == 1600);
        assert(shift_add(200, 13, 3) == 1000);
        assert(shift_add(200, 13, 8) == 2600);
        assert(shift_add(65535, 65535, 16) == 4294836225);
        assert(rows_used(13, 8) == 3);
        assert(rows_used(255, 8) == 8);
    }

    test "Booth digits of 6 are -2, +2, 0, 0 and 3 x 6 is 18" {
        assert(booth_digit(6, 0) == -2);
        assert(booth_digit(6, 1) == 2);
        assert(booth_digit(6, 2) == 0);
        assert(booth_digit(6, 3) == 0);
        assert(booth_product(3, 6, 8) == 18);
        assert(booth_partial(3, 6, 1) == 24);
    }

    test "Booth handles signs and the corners" {
        assert(booth_product(-7, 5, 8) == -35);
        assert(booth_product(127, -128, 8) == -16256);
        assert(booth_product(-128, -128, 8) == 16384);
        assert(booth_product(1234, -5678, 16) == -7006652);
        assert(booth_product(-32768, -32768, 16) == 1073741824);
        assert(booth_digit(32767, 7) == 2);
        assert(booth_digit(32767, 0) == -1);
        assert(booth_is_exact_8());
    }

    test "Booth halves the partial products" {
        assert(booth_nonzero(6, 8) == 2);
        assert(booth_nonzero(-5678, 16) == 7);
        assert(booth_nonzero(21845, 16) == 8);
        assert(booth_nonzero(32767, 16) == 2);
        assert(rows_used(32767, 16) == 15);
    }

    test "the slice takes 25 x 18 and tiles the rest" {
        assert(dsp_slices(25, 18) == 1);
        assert(dsp_slices(18, 25) == 1);
        assert(dsp_slices(16, 16) == 1);
        assert(dsp_slices(25, 25) == 2);
        assert(dsp_slices(32, 32) == 4);
        assert(dsp_slices(35, 25) == 2);
        assert(a_port(35, 25) == 18);
        assert(a_port(32, 16) == 25);
        assert(dsp_slices(48, 48) == 6);
        assert(dsp_slices(64, 64) == 12);
        assert(pieces(49, 25) == 2);
        assert(pieces(50, 25) == 3);
        assert(piece_bits(50, 25, 0) == 24);
        assert(piece_bits(50, 25, 2) == 2);
        assert(piece_bits(18, 25, 0) == 18);
        assert(piece_bits(18, 25, 1) == 0);
        assert(mults_on_200t(32, 32) == 185);
    }

    test "the accumulator has room for 2^headroom products" {
        assert(headroom(25, 18) == 5);
        assert(max_terms(25, 18) == 32.0);
        assert(acc_fits(25, 18, 32));
        assert(!acc_fits(25, 18, 33));
        assert(guard_bits(1) == 0);
        assert(guard_bits(1000) == 10);
        assert(guard_bits(1025) == 11);
        assert(acc_fits(16, 16, 65536));
        assert(!acc_fits(16, 16, 65537));
        assert(max_terms(32, 32) == 0.0);
    }

    test "VERSION says what the header says" {
        assert(VERSION == 1);
        assert(dsp_slices(DSP_A_BITS, DSP_B_BITS) == 1);
        assert(headroom(DSP_A_BITS, DSP_B_BITS) == 5);
    }
}
// phi^2 + 1/phi^2 = 3 | TRINITY
Все уроки
Модуль 1 · Сложение
Почему сложение медленное: перенос, который идёт вверх по слову, выделенная цепь в каждом слайсе, префиксные сети и деревья сохранения переноса.
Модуль 2 · Умножение
Произведение — сумма сдвинутых копий; перекодирование Бута вдвое сокращает их, а слайс DSP48E1 делает остальное одним блоком.
Модуль 3 · Фиксированная точка
Где стоит двоичная точка, что округление делает со значением и с его средним и что даёт каждый бит квантователя.
Модуль 4 · Функции в железе
Синус, косинус, угол и длина из сдвигов и сложений — и когда таблица оказывается выгоднее.
Модуль 5 · Сигналы и дискретизация
Что дискретизация делает с частотой, как генератор строится из сумматора и что измеряет бин ДПФ.
Модуль 6 · Фильтры FIR
Скользящее среднее, расчёт окном sinc с целыми коэффициентами и раскладка отводов по слайсам DSP.
Модуль 7 · Многоскоростная обработка
Понижение частоты дискретизации без заворота шума: децимация, фильтр CIC и полифазная форма.
Модуль 8 · БПФ
N log N вместо N^2: бабочки, бит-реверсный порядок входа и биты, которые добавляет каждый этап.
Модуль 9 · На стенде
От арифметики к плате: коррелятор из спеки модема, бюджет слайсов и тайминга и итоговый фильтр.