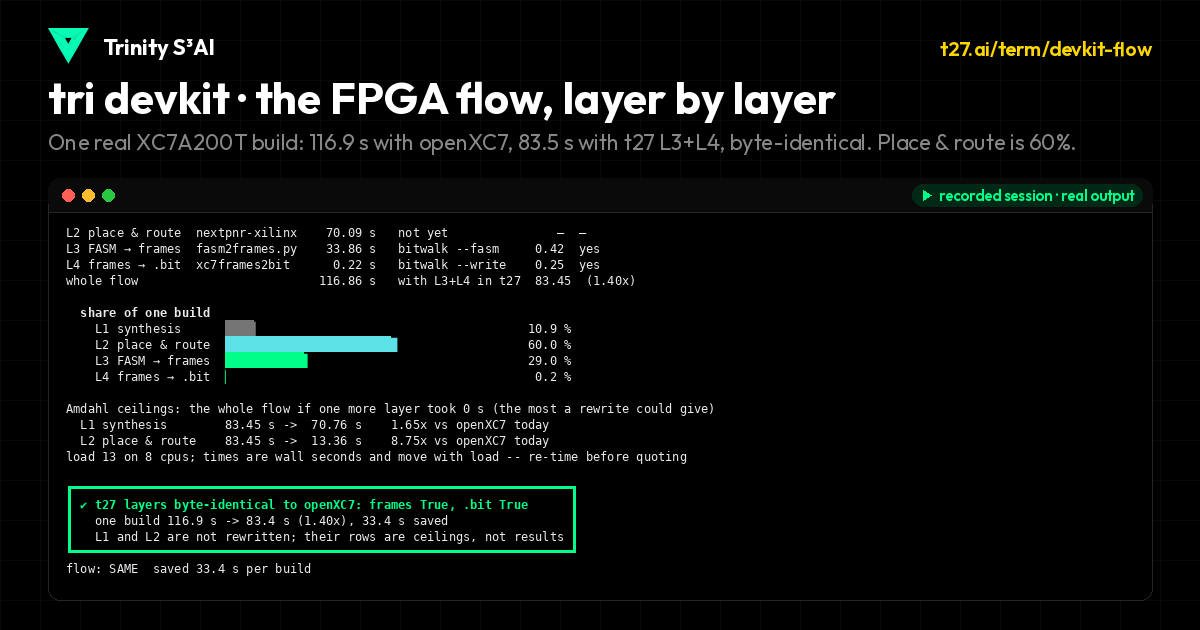
tri devkit · the FPGA flow, layer by layer
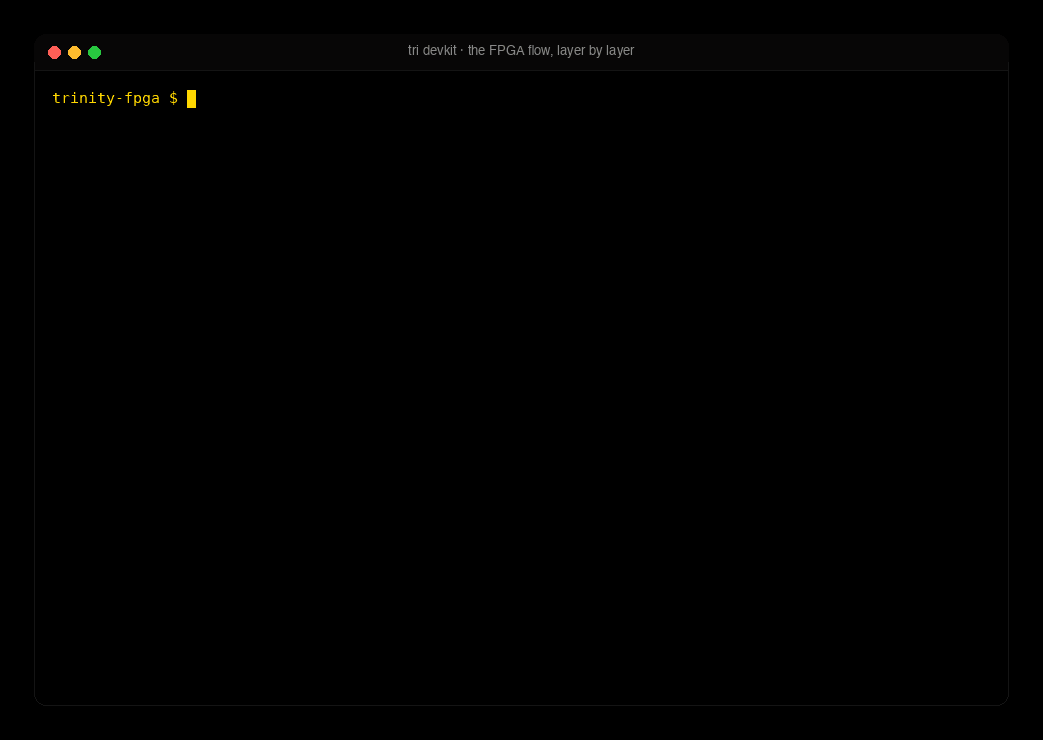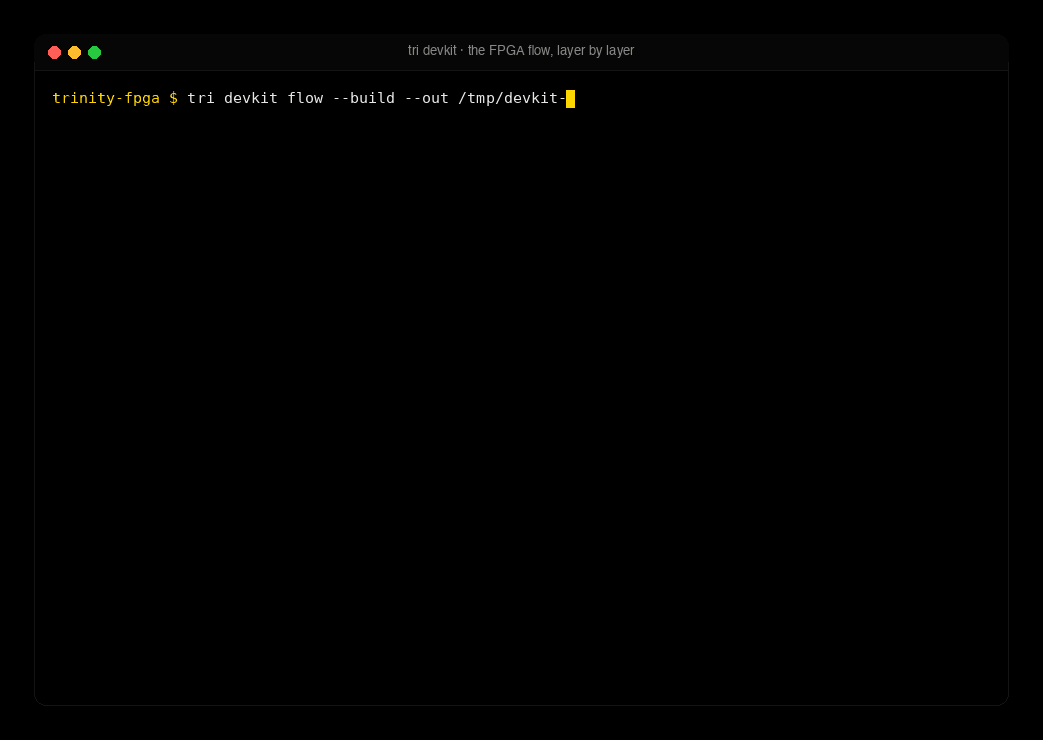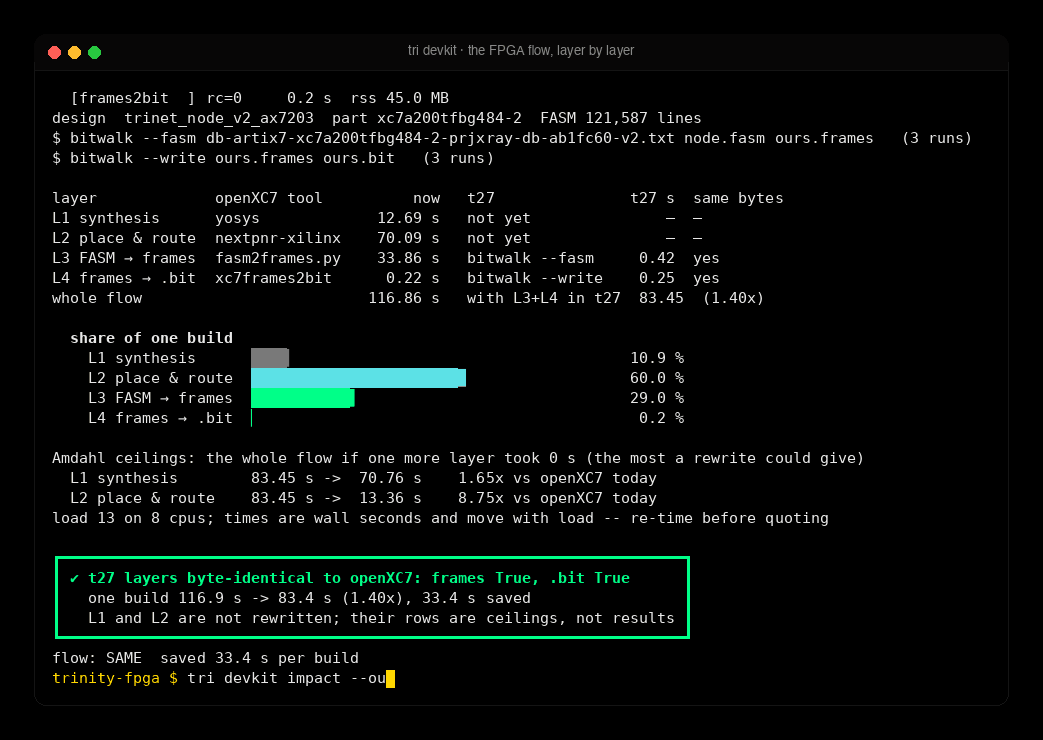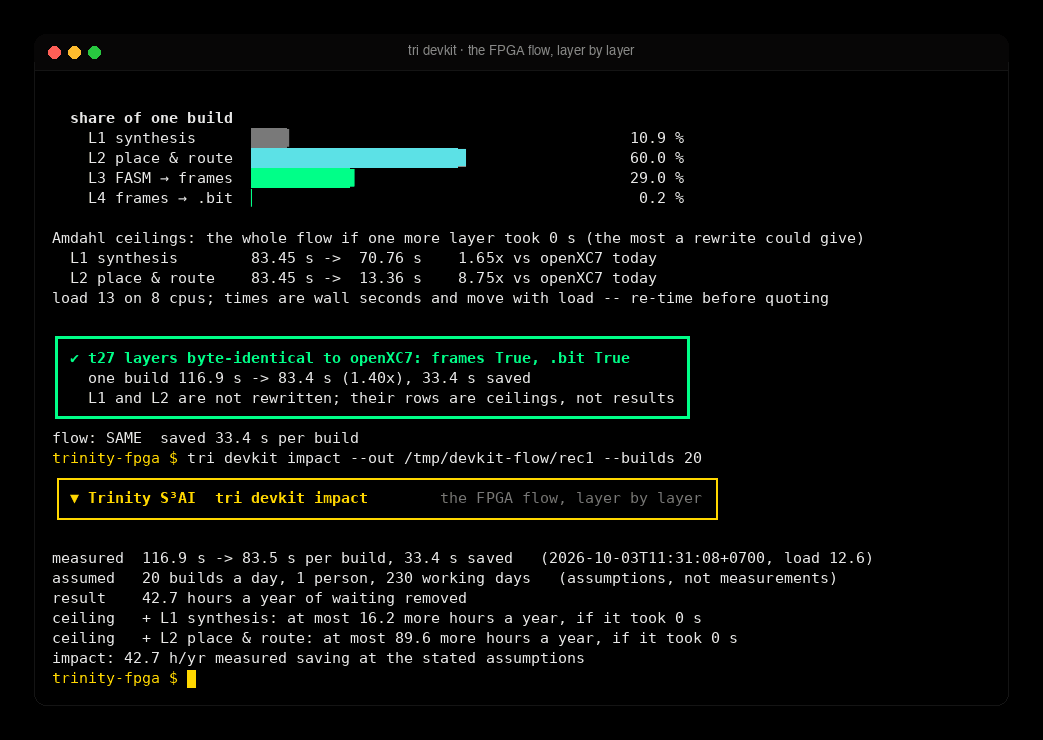
  share of one build
    L1 synthesis      ████▎                                     10.9 %
    L2 place & route  ███████████████████████▉                  60.0 %
    L3 FASM → frames  ███████████▌                              29.0 %
    L4 frames → .bit  ▏                                          0.2 %

Amdahl ceilings: the whole flow if one more layer took 0 s (the most a rewrite could give)
  L1 synthesis        83.45 s ->  70.76 s    1.65x vs openXC7 today
  L2 place & route    83.45 s ->  13.36 s    8.75x vs openXC7 today
load 13 on 8 cpus; times are wall seconds and move with load -- re-time before quoting

┏━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ ✔ t27 layers byte-identical to openXC7: frames True, .bit True      ┃
┃   one build 116.9 s -> 83.4 s (1.40x), 33.4 s saved                 ┃
┃   L1 and L2 are not rewritten; their rows are ceilings, not results ┃
┗━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━┛
flow: SAME  saved 33.4 s per build
trinity-fpga $ tri devkit impact --out /tmp/devkit-flow/rec1 --builds 20
╭────────────────────────────────────────────────────────────────────────╮
│ ▼ Trinity S³AI  tri devkit impact        the FPGA flow, layer by layer │
╰────────────────────────────────────────────────────────────────────────╯

measured  116.9 s -> 83.5 s per build, 33.4 s saved   (2026-10-03T11:31:08+0700, load 12.6)
assumed   20 builds a day, 1 person, 230 working days   (assumptions, not measurements)
result    42.7 hours a year of waiting removed
ceiling   + L1 synthesis: at most 16.2 more hours a year, if it took 0 s
ceiling   + L2 place & route: at most 89.6 more hours a year, if it took 0 s
impact: 42.7 h/yr measured saving at the stated assumptions
trinity-fpga $  Trinity S³AI