Непосредственное значение
Вы узнаете
Как 15-битное знаковое непосредственное значение обрезается, хранится и читается обратно.
Непосредственное значение живёт в 15 битах дополнительного кода: от -16384 до 16383. Спека прижимает всё, что выходит за край, к краю, а не заворачивает, поэтому 20000 превращается в 16383, а поле проходит путь encode и decode туда и обратно. Спека урока — ассемблер и дизассемблер t27a, которые пишут и читают одну и ту же таблицу в обе стороны.
Попробовать
Попробуйте 16383, 16384 и -16385; затем найдите непосредственное значение, у которого все 15 бит — единицы.
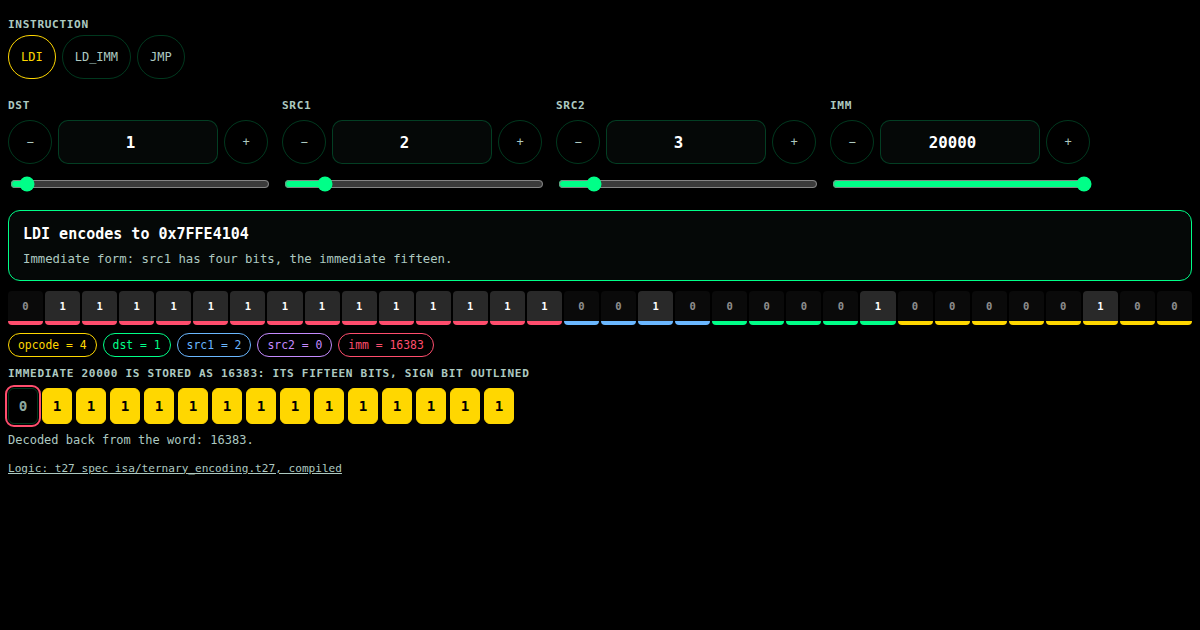
An immediate lives in 15 bits of two's complement, -16384 to 16383. Push it past the edge and watch it clamp, then decode the word back.
specs/isa/t27a.t27
// SPDX-License-Identifier: Apache-2.0
; specs/isa/t27a.t27 -- t27a, the TRI-27 assembler and disassembler, spec-level entry point
; (gHashTag/t27#6507, epic #6488; theorems T735-T736 in specs/compiler/theory/isa_round_trip.t27).
; One field table, both directions. The assembler reads a line of text and writes a word with
; t27a_encode; the disassembler reads a word with t27a_src1 / t27a_src2 / t27a_imm / v3_of and
; prints the line. Both use the t27a table of specs/isa/ternary_encoding.t27 (T736) and the
; mnemonic table of specs/isa/t27a_mnemonics.t27, so the decoder inverts the encoder by
; construction (Ramsey and Fernandez, TOPLAS 19(3), 1997), and the tests below check it over every
; opcode.
; The text form, one instruction per line. Registers are t0..t26. The immediate is decimal, with a
; leading '-' when negative.
;   immediate form (24 opcodes, SACR included):    MNEMONIC tD, tS, IMM     (tS is t0..t15)
;   three-operand form (DOT, BIND, BUNDLE2 too):  MNEMONIC tD, tS1, tS2
;   BUNDLE3:                                      BUNDLE3 tD, tS1, tS2, tV3
;   every other opcode, NOP and HALT included:    MNEMONIC tD, tS
;   any 32-bit word:                              .word N                  (N decimal, 0..4294967295)
; The disassembler prints exactly that form, with ", " between operands. A word is CANONICAL when
; its opcode byte is one of the 47, every register field it carries is 0..26, and re-encoding its
; fields gives the word back (no stray bit in an unused field). A canonical word lists as an
; instruction; every other word lists as `.word N`. That is the explicit invalid marker the issue
; asks for: the 209 undefined opcode bytes no longer read as NOP (decode_opcode still does, for the
; emulator), and since the assembler accepts `.word`, every 32-bit word round-trips.
; Why the listing is a function of a character index and not a returned string: t27 has no
; allocator, and a pure listing_char(w, k) lowers the same way to Zig, C and Verilog. The parser
; reads its characters through src_at, which takes them either from a text or from the listing of
; a word, so the round-trip tests feed the disassembler's output into the same parser that reads
; text, character by character.
; The command line is `t27c asm` / `t27c disasm` (owner-approved-foreign, 2026-10-06). It runs this
; module as `t27c gen-rust` writes it, checked in at bootstrap/gen/rust/isa/t27a.rs and held to it by
; bootstrap/tests/t27a_cli.rs; the Rust around it only splits lines and prints. The emulator side,
; gHashTag/trinity src/tri27/emu/decoder.zig, takes the same table as the `t27c gen` output of
; ternary_encoding.t27 since gHashTag/trinity#1437 (T27A_CONSUMER there).
; ASCII only (L3).
; phi^2 + 1/phi^2 = 3 | TRINITY

module T27a;

use isa::ternary_encoding;
use isa::t27a_mnemonics;

pub const REGISTERS : u32 = 27;
pub const IMM_FORM_SRC1_LIMIT : u32 = 16;
pub const LISTING_MAX : u32 = 40;
pub const KEY_MOD : u32 = 1000003;
pub const KEY_BASE : u32 = 41;

; Characters, as ASCII codes. CH_END is what src_at returns past the end of the text.
pub const CH_END : u32 = 0;
pub const CH_TAB : u32 = 9;
pub const CH_SPACE : u32 = 32;
pub const CH_COMMA : u32 = 44;
pub const CH_MINUS : u32 = 45;
pub const CH_DOT : u32 = 46;
pub const CH_ZERO : u32 = 48;
pub const CH_NINE : u32 = 57;
pub const CH_UPPER_A : u32 = 65;
pub const CH_UPPER_Z : u32 = 90;
pub const CH_UNDERSCORE : u32 = 95;
pub const CH_LOWER_A : u32 = 97;
pub const CH_LOWER_D : u32 = 100;
pub const CH_LOWER_O : u32 = 111;
pub const CH_LOWER_R : u32 = 114;
pub const CH_LOWER_T : u32 = 116;
pub const CH_LOWER_W : u32 = 119;
pub const CH_LOWER_Z : u32 = 122;

; Assembler status codes. assemble(text) is meaningful only when assemble_status(text) == ASM_OK.
pub const ASM_OK : u32 = 0;
pub const ASM_NO_MNEMONIC : u32 = 1;
pub const ASM_UNKNOWN_MNEMONIC : u32 = 2;
pub const ASM_BAD_SEPARATOR : u32 = 3;
pub const ASM_BAD_REGISTER : u32 = 4;
pub const ASM_BAD_IMMEDIATE : u32 = 5;
pub const ASM_TRAILING_TEXT : u32 = 6;
pub const ASM_BAD_WORD : u32 = 7;

; --- The operands of an opcode, from the t27a table ------------------------------------------

pub fn operand_count(op: u32) -> u32 {
    if (op == OP_BUNDLE3) { return 4; }
    if (t27a_imm_form(op)) { return 3; }
    if (t27a_src2_form(op)) { return 3; }
    return 2;
}

; Operand 1 is dst, 2 is src1, 3 is the immediate (immediate form) or src2, 4 is BUNDLE3's third.
pub fn is_imm_operand(op: u32, j: u32) -> bool {
    if (j == 3) { return t27a_imm_form(op); }
    return false;
}

pub fn reg_limit(op: u32, j: u32) -> u32 {
    if (j == 2) {
        if (t27a_imm_form(op)) { return IMM_FORM_SRC1_LIMIT; }
    }
    return REGISTERS;
}

pub fn reg_operand(w: u32, op: u32, j: u32) -> u32 {
    if (j == 1) { return dst_of(w); }
    if (j == 2) { return t27a_src1(w, op); }
    if (j == 3) { return t27a_src2(w, op); }
    return v3_of(w, op);
}

; --- Which words are instructions -------------------------------------------------------------

pub fn is_canonical(w: u32) -> bool {
    var op : u32 = opcode_of(w);
    if (is_valid(strict_decode(op)) == false) { return false; }
    if (dst_of(w) >= REGISTERS) { return false; }
    if (t27a_src1(w, op) >= reg_limit(op, 2)) { return false; }
    if (t27a_src2_form(op)) {
        if (t27a_src2(w, op) >= REGISTERS) { return false; }
    }
    if (op == OP_BUNDLE3) {
        if (v3_of(w, op) >= REGISTERS) { return false; }
    }
    return t27a_encode(op, dst_of(w), t27a_src1(w, op), t27a_src2(w, op), v3_of(w, op), t27a_imm(w, op)) == w;
}

; --- Decimal digits ---------------------------------------------------------------------------

pub fn dec_len(v: u32) -> u32 {
    var n : u32 = 1;
    var x : u32 = v;
    while (x >= 10) {
        x = x / 10;
        n = n + 1;
    }
    return n;
}

; Digit j (0 = most significant) of v written with len digits.
pub fn dec_char(v: u32, len: u32, j: u32) -> u32 {
    var x : u32 = v;
    var s : u32 = len - 1 - j;
    while (s > 0) {
        x = x / 10;
        s = s - 1;
    }
    return CH_ZERO + (x % 10);
}

; --- The disassembler: the listing of a word, one character at a time -------------------------

pub fn imm_magnitude(w: u32, op: u32) -> u32 {
    var v : i32 = t27a_imm(w, op);
    if (v < 0) { return (0 - v) as u32; }
    return v as u32;
}

pub fn operand_len(w: u32, op: u32, j: u32) -> u32 {
    if (is_imm_operand(op, j)) {
        if (t27a_imm(w, op) < 0) { return 1 + dec_len(imm_magnitude(w, op)); }
        return dec_len(imm_magnitude(w, op));
    }
    return 1 + dec_len(reg_operand(w, op, j));
}

pub fn operand_char(w: u32, op: u32, j: u32, q: u32) -> u32 {
    if (is_imm_operand(op, j)) {
        var mag : u32 = imm_magnitude(w, op);
        if (t27a_imm(w, op) < 0) {
            if (q == 0) { return CH_MINUS; }
            return dec_char(mag, dec_len(mag), q - 1);
        }
        return dec_char(mag, dec_len(mag), q);
    }
    var r : u32 = reg_operand(w, op, j);
    if (q == 0) { return CH_LOWER_T; }
    return dec_char(r, dec_len(r), q - 1);
}

; `.word N` -- the listing of a word that is not an instruction.
pub fn word_listing_char(w: u32, k: u32) -> u32 {
    if (k == 0) { return CH_DOT; }
    if (k == 1) { return CH_LOWER_W; }
    if (k == 2) { return CH_LOWER_O; }
    if (k == 3) { return CH_LOWER_R; }
    if (k == 4) { return CH_LOWER_D; }
    if (k == 5) { return CH_SPACE; }
    var n : u32 = dec_len(w);
    if (k - 6 < n) { return dec_char(w, n, k - 6); }
    return CH_END;
}

; Character k of the listing of w; CH_END past its end.
pub fn listing_char(w: u32, k: u32) -> u32 {
    if (is_canonical(w) == false) { return word_listing_char(w, k); }
    var op : u32 = opcode_of(w);
    var name : string = OPCODE_NAMES[index_of(op)];
    if (k < name.len) { return name[k] as u32; }
    var pos : u32 = 0;
    while (pos < name.len) { pos = pos + 1; }
    var count : u32 = operand_count(op);
    var j : u32 = 1;
    while (j <= count) {
        if (j == 1) {
            if (k == pos) { return CH_SPACE; }
            pos = pos + 1;
        } else {
            if (k == pos) { return CH_COMMA; }
            if (k == pos + 1) { return CH_SPACE; }
            pos = pos + 2;
        }
        var len : u32 = operand_len(w, op, j);
        if (k < pos + len) { return operand_char(w, op, j, k - pos); }
        pos = pos + len;
        j = j + 1;
    }
    return CH_END;
}

pub fn listing_len(w: u32) -> u32 {
    var k : u32 = 0;
    while (k < LISTING_MAX) {
        if (listing_char(w, k) == CH_END) { return k; }
        k = k + 1;
    }
    return LISTING_MAX;
}

; Does the listing of w read exactly `text`?
pub fn listing_is(w: u32, text: string) -> bool {
    var k : u32 = 0;
    while (k < text.len) {
        if (listing_char(w, k) != (text[k] as u32)) { return false; }
        k = k + 1;
    }
    return listing_char(w, k) == CH_END;
}

; --- The assembler: one line of text to one word ----------------------------------------------

; Character k of the source: of `text`, or, when from_word, of the listing of w.
pub fn src_at(text: string, w: u32, from_word: bool, k: u32) -> u32 {
    if (from_word) { return listing_char(w, k); }
    if (k < text.len) { return text[k] as u32; }
    return CH_END;
}

pub fn is_space(c: u32) -> bool {
    if (c == CH_SPACE) { return true; }
    return c == CH_TAB;
}

pub fn is_digit(c: u32) -> bool {
    if (c < CH_ZERO) { return false; }
    return c <= CH_NINE;
}

; Mnemonic characters. Lower case is read so that `add` is an unknown mnemonic, not a missing one.
pub fn is_name_char(c: u32) -> bool {
    if (is_digit(c)) { return true; }
    if (c == CH_UNDERSCORE) { return true; }
    if (c >= CH_UPPER_A) {
        if (c <= CH_UPPER_Z) { return true; }
    }
    if (c >= CH_LOWER_A) {
        if (c <= CH_LOWER_Z) { return true; }
    }
    return false;
}

pub fn skip_spaces(text: string, w: u32, from_word: bool, k: u32) -> u32 {
    var i : u32 = k;
    while (is_space(src_at(text, w, from_word, i))) { i = i + 1; }
    return i;
}

pub fn name_end(text: string, w: u32, from_word: bool, k: u32) -> u32 {
    var i : u32 = k;
    while (is_name_char(src_at(text, w, from_word, i))) { i = i + 1; }
    return i;
}

pub fn digits_end(text: string, w: u32, from_word: bool, k: u32) -> u32 {
    var i : u32 = k;
    while (is_digit(src_at(text, w, from_word, i))) { i = i + 1; }
    return i;
}

; Callers bound the digit count first (registers 2, immediates 5) or check dec_fits_u32.
pub fn dec_value(text: string, w: u32, from_word: bool, k: u32, e: u32) -> u32 {
    var v : u32 = 0;
    var i : u32 = k;
    while (i < e) {
        v = v * 10 + (src_at(text, w, from_word, i) - CH_ZERO);
        i = i + 1;
    }
    return v;
}

pub fn dec_fits_u32(text: string, w: u32, from_word: bool, k: u32, e: u32) -> bool {
    var v : u32 = 0;
    var i : u32 = k;
    while (i < e) {
        var d : u32 = src_at(text, w, from_word, i) - CH_ZERO;
        if (v > 429496729) { return false; }
        if (v == 429496729) {
            if (d > 5) { return false; }
        }
        v = v * 10 + d;
        i = i + 1;
    }
    return true;
}

; A key of a mnemonic, so the source is read once and compared with one candidate name, not 47.
pub fn key_step(key: u32, c: u32) -> u32 {
    return (key * KEY_BASE + c) % KEY_MOD;
}

pub fn name_key(name: string) -> u32 {
    var key : u32 = 0;
    var i : u32 = 0;
    while (i < name.len) {
        key = key_step(key, name[i] as u32);
        i = i + 1;
    }
    return key;
}

pub fn src_key(text: string, w: u32, from_word: bool, k: u32, e: u32) -> u32 {
    var key : u32 = 0;
    var i : u32 = k;
    while (i < e) {
        key = key_step(key, src_at(text, w, from_word, i));
        i = i + 1;
    }
    return key;
}

pub fn same_name(name: string, text: string, w: u32, from_word: bool, k: u32, e: u32) -> bool {
    var n : u32 = 0;
    while (n < name.len) { n = n + 1; }
    if (e - k != n) { return false; }
    var i : u32 = 0;
    while (i < n) {
        if ((name[i] as u32) != src_at(text, w, from_word, k + i)) { return false; }
        i = i + 1;
    }
    return true;
}

; Table index 0..46 of the mnemonic in [k, e); NO_INDEX when it names no opcode.
pub fn mnemonic_index(text: string, w: u32, from_word: bool, k: u32, e: u32) -> u32 {
    var key : u32 = src_key(text, w, from_word, k, e);
    var i : u32 = 0;
    while (i < OPCODE_COUNT) {
        var name : string = OPCODE_NAMES[i];
        if (name_key(name) == key) {
            if (same_name(name, text, w, from_word, k, e)) { return i; }
        }
        i = i + 1;
    }
    return NO_INDEX;
}

pub fn fail(code: u32, want_status: bool) -> u32 {
    if (want_status) { return code; }
    return 0;
}

; `.word N`, starting at the dot at k.
pub fn parse_word_directive(text: string, w: u32, from_word: bool, k: u32, want_status: bool) -> u32 {
    if (src_at(text, w, from_word, k + 1) != CH_LOWER_W) { return fail(ASM_UNKNOWN_MNEMONIC, want_status); }
    if (src_at(text, w, from_word, k + 2) != CH_LOWER_O) { return fail(ASM_UNKNOWN_MNEMONIC, want_status); }
    if (src_at(text, w, from_word, k + 3) != CH_LOWER_R) { return fail(ASM_UNKNOWN_MNEMONIC, want_status); }
    if (src_at(text, w, from_word, k + 4) != CH_LOWER_D) { return fail(ASM_UNKNOWN_MNEMONIC, want_status); }
    var p : u32 = skip_spaces(text, w, from_word, k + 5);
    if (p == k + 5) { return fail(ASM_BAD_SEPARATOR, want_status); }
    var de : u32 = digits_end(text, w, from_word, p);
    if (de == p) { return fail(ASM_BAD_WORD, want_status); }
    if (de - p > 10) { return fail(ASM_BAD_WORD, want_status); }
    if (dec_fits_u32(text, w, from_word, p, de) == false) { return fail(ASM_BAD_WORD, want_status); }
    var v : u32 = dec_value(text, w, from_word, p, de);
    var e : u32 = skip_spaces(text, w, from_word, de);
    if (src_at(text, w, from_word, e) != CH_END) { return fail(ASM_TRAILING_TEXT, want_status); }
    if (want_status) { return ASM_OK; }
    return v;
}

; The one parser. want_status selects what it returns: the status code, or the word.
pub fn parse(text: string, w: u32, from_word: bool, want_status: bool) -> u32 {
    var k : u32 = skip_spaces(text, w, from_word, 0);
    if (src_at(text, w, from_word, k) == CH_DOT) { return parse_word_directive(text, w, from_word, k, want_status); }
    var e : u32 = name_end(text, w, from_word, k);
    if (e == k) { return fail(ASM_NO_MNEMONIC, want_status); }
    var idx : u32 = mnemonic_index(text, w, from_word, k, e);
    if (idx >= OPCODE_COUNT) { return fail(ASM_UNKNOWN_MNEMONIC, want_status); }
    var op : u32 = opcode_at(idx);
    var count : u32 = operand_count(op);
    var dst : u32 = 0;
    var s1 : u32 = 0;
    var s2 : u32 = 0;
    var v3 : u32 = 0;
    var imm : i32 = 0;
    var j : u32 = 1;
    k = e;
    while (j <= count) {
        if (j == 1) {
            var after : u32 = skip_spaces(text, w, from_word, k);
            if (after == k) { return fail(ASM_BAD_SEPARATOR, want_status); }
            k = after;
        } else {
            k = skip_spaces(text, w, from_word, k);
            if (src_at(text, w, from_word, k) != CH_COMMA) { return fail(ASM_BAD_SEPARATOR, want_status); }
            k = skip_spaces(text, w, from_word, k + 1);
        }
        if (is_imm_operand(op, j)) {
            var neg : bool = false;
            if (src_at(text, w, from_word, k) == CH_MINUS) {
                neg = true;
                k = k + 1;
            }
            var de : u32 = digits_end(text, w, from_word, k);
            if (de == k) { return fail(ASM_BAD_IMMEDIATE, want_status); }
            if (de - k > 5) { return fail(ASM_BAD_IMMEDIATE, want_status); }
            var mag : u32 = dec_value(text, w, from_word, k, de);
            if (neg) {
                if (mag > 16384) { return fail(ASM_BAD_IMMEDIATE, want_status); }
                imm = 0 - (mag as i32);
            } else {
                if (mag > 16383) { return fail(ASM_BAD_IMMEDIATE, want_status); }
                imm = mag as i32;
            }
            k = de;
        } else {
            if (src_at(text, w, from_word, k) != CH_LOWER_T) { return fail(ASM_BAD_REGISTER, want_status); }
            var re : u32 = digits_end(text, w, from_word, k + 1);
            if (re == k + 1) { return fail(ASM_BAD_REGISTER, want_status); }
            if (re - k > 3) { return fail(ASM_BAD_REGISTER, want_status); }
            var r : u32 = dec_value(text, w, from_word, k + 1, re);
            if (r >= reg_limit(op, j)) { return fail(ASM_BAD_REGISTER, want_status); }
            if (j == 1) { dst = r; }
            if (j == 2) { s1 = r; }
            if (j == 3) { s2 = r; }
            if (j == 4) { v3 = r; }
            k = re;
        }
        j = j + 1;
    }
    k = skip_spaces(text, w, from_word, k);
    if (src_at(text, w, from_word, k) != CH_END) { return fail(ASM_TRAILING_TEXT, want_status); }
    if (want_status) { return ASM_OK; }
    return t27a_encode(op, dst, s1, s2, v3, imm);
}

; --- The entry points ---------------------------------------------------------------------------

pub fn assemble(text: string) -> u32 {
    return parse(text, 0, false, false);
}

pub fn assemble_status(text: string) -> u32 {
    return parse(text, 0, false, true);
}

; Disassemble w and assemble the listing again, without leaving the character stream.
pub fn reassemble(w: u32) -> u32 {
    return parse("", w, true, false);
}

pub fn reassemble_status(w: u32) -> u32 {
    return parse("", w, true, true);
}

invariant the_text_form_fits_the_word {
    assert REGISTERS == 27;
    assert IMM_FORM_SRC1_LIMIT == SRC1_MASK_IMM_FORM + 1;
    assert REGISTERS <= REG_MASK + 1;
    assert IMM_MAX == 16383;
    assert IMM_MIN == 0 - 16384;
    assert KEY_MOD * KEY_BASE + 255 < 4294967295;
}

; The words the pinned spec already pins, read from text.
test assembles_the_words_the_encoding_spec_pins {
    assert assemble_status("ADD t3, t1, t2") == ASM_OK;
    assert assemble("ADD t3, t1, t2") == 533264;
    assert assemble("LDI t3, t0, -5") == 4294312708;
    assert assemble("MOV t3, t1") == 8975;
    assert assemble("JGT t2, t1, 7") == 926276;
    assert assemble("BUNDLE3 t3, t1, t2, t4") == 34087779;
    assert assemble("BUNDLE3 t3, t1, t2, t4") == bundle3_word(3, 1, 2, 4);
    assert assemble("NOP t0, t0") == 0;
    assert assemble("HALT t0, t0") == OP_HALT;
}

; And the other way: those words list as that text.
test lists_the_words_the_encoding_spec_pins {
    assert listing_is(533264, "ADD t3, t1, t2");
    assert listing_is(4294312708, "LDI t3, t0, -5");
    assert listing_is(8975, "MOV t3, t1");
    assert listing_is(926276, "JGT t2, t1, 7");
    assert listing_is(34087779, "BUNDLE3 t3, t1, t2, t4");
    assert listing_is(0, "NOP t0, t0");
    assert listing_is(533264, "ADD t3, t1, t2 ") == false;
    assert listing_is(533264, "ADD t3, t1, t") == false;
    assert listing_len(533264) == 14;
}

; T736 through t27a: the five opcodes T735 found broken keep every operand, as text.
test the_five_widened_opcodes_round_trip_as_text {
    assert listing_is(assemble("DOT t3, t1, t2"), "DOT t3, t1, t2");
    assert listing_is(assemble("BIND t26, t0, t26"), "BIND t26, t0, t26");
    assert listing_is(assemble("BUNDLE2 t3, t1, t9"), "BUNDLE2 t3, t1, t9");
    assert listing_is(assemble("BUNDLE3 t26, t25, t24, t23"), "BUNDLE3 t26, t25, t24, t23");
    assert listing_is(assemble("SACR t4, t1, 3"), "SACR t4, t1, 3");
    assert listing_is(assemble("SACR t4, t15, -16384"), "SACR t4, t15, -16384");
    assert t27a_src2(assemble("DOT t3, t1, t2"), OP_DOT) == 2;
    assert t27a_imm(assemble("SACR t4, t1, 3"), OP_SACR) == 3;
    assert v3_of(assemble("BUNDLE3 t26, t25, t24, t23"), OP_BUNDLE3) == 23;
}

pub fn sample_reg(k: u32, limit: u32) -> u32 {
    var m : u32 = k % 3;
    if (m == 0) { return 0; }
    if (m == 1) { return limit / 2; }
    return limit - 1;
}

pub fn sample_imm(k: u32) -> i32 {
    var m : u32 = k % 5;
    if (m == 0) { return IMM_MIN; }
    if (m == 1) { return 0 - 1; }
    if (m == 2) { return 0; }
    if (m == 3) { return 1; }
    return IMM_MAX;
}

; Operand sample k of opcode op, read back from the word w: does every operand the opcode carries
; come back as it went in?
pub fn keeps_operands(w: u32, op: u32, k: u32) -> bool {
    if (opcode_of(w) != op) { return false; }
    if (dst_of(w) != sample_reg(k, REGISTERS)) { return false; }
    if (t27a_src1(w, op) != sample_reg(k / 3, reg_limit(op, 2))) { return false; }
    if (t27a_src2_form(op)) {
        if (t27a_src2(w, op) != sample_reg(k / 9, REGISTERS)) { return false; }
    }
    if (op == OP_BUNDLE3) {
        if (v3_of(w, op) != sample_reg(k / 27, REGISTERS)) { return false; }
    }
    if (t27a_imm_form(op)) {
        if (t27a_imm(w, op) != sample_imm(k / 81)) { return false; }
    }
    return true;
}

; The MVP's round-trip test over every opcode: for each of the 47 and each of 3^4 x 5 operand
; samples (registers at both ends and the middle, the immediate at both ends, -1, 0, 1), the
; encoded word is canonical, its listing assembles without error, back to the same word, and the
; word read back carries every operand the opcode takes.
test every_opcode_round_trips_through_its_listing {
    var idx : u32 = 0;
    var words : u32 = 0;
    var back : u32 = 0;
    var ops_ok : u32 = 0;
    while (idx < OPCODE_COUNT) {
        var op : u32 = opcode_at(idx);
        var this_ok : u32 = 0;
        var k : u32 = 0;
        while (k < 405) {
            var w : u32 = t27a_encode(op, sample_reg(k, REGISTERS), sample_reg(k / 3, reg_limit(op, 2)), sample_reg(k / 9, REGISTERS), sample_reg(k / 27, REGISTERS), sample_imm(k / 81));
            if (is_canonical(w)) {
                if (reassemble_status(w) == ASM_OK) {
                    if (reassemble(w) == w) {
                        if (keeps_operands(reassemble(w), op, k)) {
                            back = back + 1;
                            this_ok = this_ok + 1;
                        }
                    }
                }
            }
            words = words + 1;
            k = k + 1;
        }
        if (this_ok == 405) { ops_ok = ops_ok + 1; }
        idx = idx + 1;
    }
    assert words == 47 * 405;
    assert back == words;
    assert ops_ok == 47;
}

; The disassembler can tell NOP from garbage: of the 256 one-byte words, the 47 opcode bytes list
; as instructions and the 209 others as `.word`, and every one of them assembles back.
test undefined_bytes_list_as_word_not_nop {
    var b : u32 = 0;
    var dotted : u32 = 0;
    var named : u32 = 0;
    var back : u32 = 0;
    while (b < 256) {
        if (listing_char(b, 0) == CH_DOT) { dotted = dotted + 1; } else { named = named + 1; }
        if (reassemble(b) == b) { back = back + 1; }
        b = b + 1;
    }
    assert dotted == UNDEFINED_BYTES;
    assert named == OPCODE_COUNT;
    assert back == 256;
    assert decode_opcode(1) == OP_NOP;
    assert listing_is(1, ".word 1");
    assert listing_is(0, "NOP t0, t0");
    assert listing_is(255, ".word 255");
}

; A word with a defined opcode but a stray bit or an out-of-range register is not an instruction.
test non_canonical_words_list_as_word {
    assert is_canonical(8975);
    assert is_canonical(8975 + 2147483648) == false;
    assert listing_is(8975 + 2147483648, ".word 2147492623");
    assert is_canonical(OP_MOV | (27 << DST_SHIFT)) == false;
    assert is_canonical(OP_ADD | (31 << SRC2_SHIFT)) == false;
    assert is_canonical(OP_MOV | (1 << SRC2_SHIFT)) == false;
    assert is_canonical(OP_BUNDLE3 | (27 << V3_SHIFT)) == false;
    assert is_canonical(OP_SACR | (15 << SRC1_SHIFT)) == true;
    assert listing_is(4294967295, ".word 4294967295");
}

; Every 32-bit word round-trips, instruction or not: 4096 words from a full-period LCG plus the
; extremes.
test every_word_round_trips_canonical_or_not {
    var x : u32 = 12345;
    var i : u32 = 0;
    var back : u32 = 0;
    var canonical : u32 = 0;
    while (i < 4096) {
        x = (x % 65536) * 40503 + (x / 65536) + 1;
        if (reassemble(x) == x) { back = back + 1; }
        if (is_canonical(x)) { canonical = canonical + 1; }
        i = i + 1;
    }
    assert back == 4096;
    assert canonical < 4096;
    assert reassemble(0) == 0;
    assert reassemble(4294967295) == 4294967295;
    assert reassemble_status(4294967295) == ASM_OK;
}

; Ill-formed text is refused, each with its own status.
test the_assembler_refuses_ill_formed_text {
    assert assemble_status("") == ASM_NO_MNEMONIC;
    assert assemble_status("   ") == ASM_NO_MNEMONIC;
    assert assemble_status("FOO t1, t2") == ASM_UNKNOWN_MNEMONIC;
    assert assemble_status("add t3, t1, t2") == ASM_UNKNOWN_MNEMONIC;
    assert assemble_status("ADD3X t1, t2") == ASM_UNKNOWN_MNEMONIC;
    assert assemble_status(".wordx 5") == ASM_BAD_SEPARATOR;
    assert assemble_status(".byte 5") == ASM_UNKNOWN_MNEMONIC;
    assert assemble_status("ADD") == ASM_BAD_SEPARATOR;
    assert assemble_status("ADD t3, t1") == ASM_BAD_SEPARATOR;
    assert assemble_status("ADD t3 t1, t2") == ASM_BAD_SEPARATOR;
    assert assemble_status("ADD t27, t1, t2") == ASM_BAD_REGISTER;
    assert assemble_status("ADD t3, r1, t2") == ASM_BAD_REGISTER;
    assert assemble_status("ADD t3, t, t2") == ASM_BAD_REGISTER;
    assert assemble_status("ADD t3, t100, t2") == ASM_BAD_REGISTER;
    assert assemble_status("LDI t3, t16, 0") == ASM_BAD_REGISTER;
    assert assemble_status("SACR t4, t16, 0") == ASM_BAD_REGISTER;
    assert assemble_status("SACR t4, t15, 0") == ASM_OK;
    assert assemble_status("LDI t3, t0, 16384") == ASM_BAD_IMMEDIATE;
    assert assemble_status("LDI t3, t0, -16385") == ASM_BAD_IMMEDIATE;
    assert assemble_status("LDI t3, t0, -16384") == ASM_OK;
    assert assemble_status("LDI t3, t0, 100000") == ASM_BAD_IMMEDIATE;
    assert assemble_status("LDI t3, t0, -") == ASM_BAD_IMMEDIATE;
    assert assemble_status("ADD t3, t1, t2, t4") == ASM_TRAILING_TEXT;
    assert assemble_status("MOV t3, t1 x") == ASM_TRAILING_TEXT;
    assert assemble_status(".word 4294967296") == ASM_BAD_WORD;
    assert assemble_status(".word 99999999999") == ASM_BAD_WORD;
    assert assemble_status(".word") == ASM_BAD_SEPARATOR;
    assert assemble_status(".word 5 6") == ASM_TRAILING_TEXT;
    assert assemble(".word 4294967295") == 4294967295;
    assert assemble(".word 0") == 0;
}

; The mnemonic match does not lean on the key: a name matches only its own exact span of text.
test a_mnemonic_matches_only_its_exact_span {
    assert same_name("ADD", "ADD3", 0, false, 0, 3);
    assert same_name("ADD", "ADD3", 0, false, 0, 4) == false;
    assert same_name("ADD3", "ADD", 0, false, 0, 3) == false;
    assert same_name("ADD", "SUB", 0, false, 0, 3) == false;
    assert mnemonic_index("ADD3", 0, false, 0, 4) == index_of(OP_ADD3);
    assert mnemonic_index("ADD3", 0, false, 0, 3) == index_of(OP_ADD);
    assert mnemonic_index("ADD", 0, false, 0, 2) == NO_INDEX;
}

; Spacing is free around the separators; the listing is the canonical spelling.
test the_assembler_reads_free_spacing {
    assert assemble("  ADD   t3 ,t1,   t2  ") == 533264;
    assert assemble("ADD\tt3,\tt1, t2") == 533264;
    assert assemble("LDI t3, t0,-5") == 4294312708;
    assert assemble(".word   8975 ") == 8975;
    assert listing_is(assemble("  ADD   t3 ,t1,   t2  "), "ADD t3, t1, t2");
}
Все уроки
Модуль 1 · Три значения
Почему три, как сбалансированная троичная система пишет любое число без знака и что дают переворот и отсечение тритов.
Модуль 2 · Логика с «не знаю»
Трёхзначные вентили Клини, два вентиля без двоичного двойника и сложение как пара таблиц.
Модуль 3 · Складываем триты
Полусумматор, полный сумматор и перенос, бегущий влево разряд за разрядом.
Модуль 4 · Умножение без умножителя
Копия, ноль или переворот: произведение на один трит, умножение столбиком и MAC, который только складывает.
Модуль 5 · Триты в двоичной памяти
Два бита на трит, пять тритов на байт и сколько бит нужно слову из 27 тритов.
Модуль 6 · Командное слово TRI-27
32-битное слово, которое декодирует эмулятор Trinity: его поля, 47 опкодов и 15-битное непосредственное значение.
Модуль 7 · Троичная машина
АЛУ из сумматоров этого курса, переход на три стороны и программа, которую можно пройти по шагам.
Модуль 8 · Три ответа
Сравнение по старшему различному триту, поиск числа по третям и сортировка трёхзначными сравнениями.
Модуль 9 · Троичные нейроны
Веса -1, 0, +1: один нейрон, детектор и маленький слой, и нигде нет умножителя.