The carry chain
You will learn
Why a carry walks the whole word, and how the dedicated chain of a slice makes the walk cheap.
Bit i of a + b is the XOR of a_i, b_i and the carry into it, and the carry out is their majority. A carry made at bit 0 of 127 + 1 has to pass through bits 1 to 6 before the top bit knows its answer: the widget lights that run of 7. Recomputing the carry in a LUT costs a LUT and a route per bit; the dedicated chain of a 7-series slice costs one LUT and one route, then one hop per bit, in CARRY4 blocks of 4 bits. The spec adders.t27 states both models and leaves the three delays to you.
Try it
Load 127 + 1 and find the longest carry run; then switch to 85 + 170 and explain why the run is 0. Set the hop to 30 ps and compare the two delays for 32 bits.
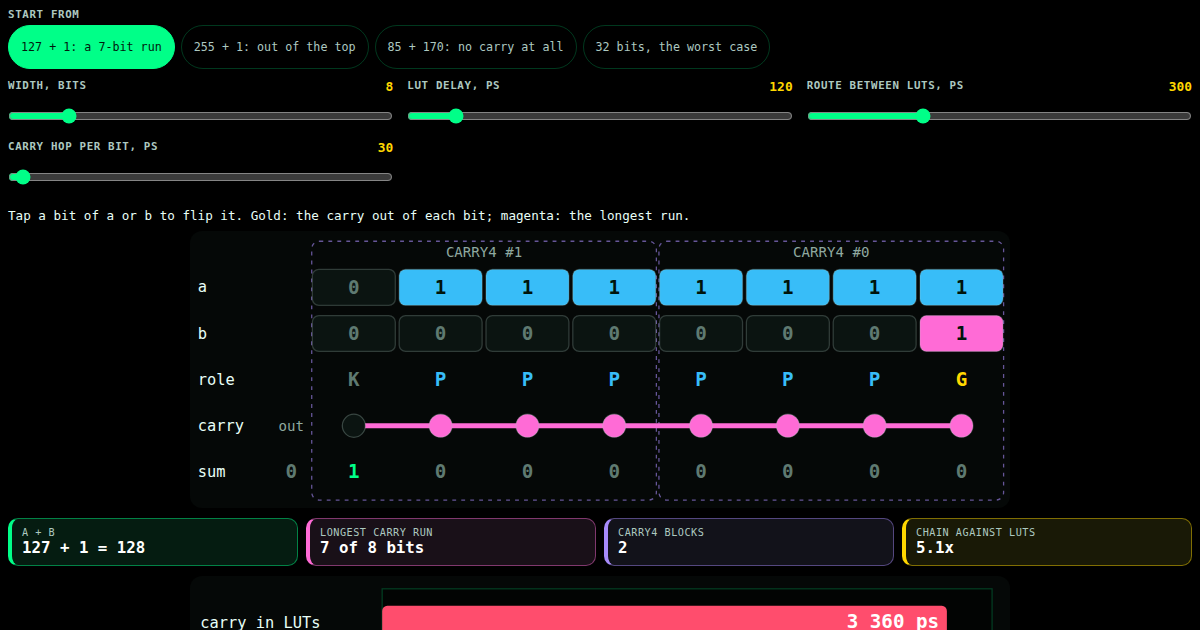
Tap the bits of two numbers and watch the carry run up the word. Then set three delays and see what the dedicated carry chain saves over LUTs.
specs/fpga/dsp/adders.t27
// SPDX-License-Identifier: Apache-2.0
// specs/fpga/dsp/adders.t27 -- adding numbers in hardware: the carry chain, prefix networks, carry-save trees
// Host: gHashTag/trinity apps/website public/widgets/{carry-chain,prefix-adder,csa-tree}/ (module 1 of the
//       course arithmetic-and-dsp): each widget's logic.js is these fn bodies compiled to wasm
//       (scripts/t27-logic.mjs in gHashTag/999-multibots-telegraf, types stripped); the pages
//       write no formula of their own.
//
// THE CARRY CHAIN. Bit i of a + b is a_i XOR b_i XOR c_i, and the carry out of bit i is the
// majority of a_i, b_i and c_i (c_0 = 0). A carry generated at one bit travels up through every
// bit that propagates it (a_i XOR b_i = 1), so the wait for the top bit grows with the width.
// The FPGA answer is a dedicated chain: one LUT per bit forms propagate and generate, and the
// carry then hops through a multiplexer per bit with no general routing between bits. On a
// 7-series device the chain comes in CARRY4 blocks of 4 bits, one per slice (Xilinx UG474,
// "7 Series FPGAs CLB User Guide", carry logic). The delay model below is the teaching model:
// a carry recomputed by a LUT pays a LUT and a route per bit; the dedicated chain pays one LUT
// and one route, then one hop per bit. Every delay is an input the reader sets; no number here
// is a datasheet figure.
//
// PREFIX NETWORKS (D. Harris, "A taxonomy of parallel prefix networks", Asilomar 2003). The
// carries are prefixes of an associative operator, so they can be computed as a tree. src()
// says, for every column i and logic level, which column it combines with (-1: none):
//   serial (ripple)   level l joins column l+1 to column l        n - 1 levels, n - 1 cells
//   Sklansky          bit l of i set: i joins (i >> l << l) - 1    log2 n levels, (n/2) log2 n cells
//   Kogge-Stone       i >= 2^l: i joins i - 2^l                    log2 n levels, n log2 n - n + 1 cells
//   Brent-Kung        an up-sweep and a down-sweep                 2 log2 n - 1 levels, 2n - 2 - log2 n cells
// covers() replays the network on the spans [lo..i] and checks every column ends at [0..i]:
// the network computes every carry, not just the counts.
//
// CARRY-SAVE TREES. A 3:2 counter (a full adder per bit) turns three numbers into two -- a sum
// word a ^ b ^ c and a carry word majority(a, b, c) << 1 -- with no carry propagation at all.
// k operands need csa_levels(k) layers of them before one carry-propagate adder; the Dadda
// heights 2, 3, 4, 6, 9, 13, 19, 28, 42, 63 (d(j+1) = floor(3 d(j) / 2); L. Dadda, "Some
// schemes for parallel multipliers", Alta Frequenza 34, 1965) are the most operands j layers
// can reduce to two. wallace_next() is one layer of the Wallace reduction (C. S. Wallace, IEEE
// Trans. Electronic Computers EC-13, 1964); the tests hold the two counts equal.
//
// WHAT IT DOES NOT CLAIM: no device timing. Fanout and wire length cost real delay that the
// level count does not show; max_fanout() names the first of them.
// Claim status: checked by the tests below -- the sum of 100 + 27, the 7-bit run of 127 + 1,
// the four prefix networks verified to compute every carry for n = 2..32 and their cell
// counts equal to the closed forms, the Dadda sequence, and Wallace = Dadda levels for k <= 300.
// phi^2 + 1/phi^2 = 3 | TRINITY

module fpga::dsp::adders {

    pub const KIND : str = "widget-logic";
    pub const ID : str = "adders";
    pub const VERSION : u8 = 1;
    pub const CARRY4_BITS : u8 = 4;
    pub const MAX_BITS : u8 = 32;
    pub const NET_RIPPLE : u8 = 0;
    pub const NET_SKLANSKY : u8 = 1;
    pub const NET_KOGGE_STONE : u8 = 2;
    pub const NET_BRENT_KUNG : u8 = 3;
    pub const DADDA_FIRST : u16 = 2;

    // ---- The carry chain -------------------------------------------------------------------

    // The carry out of bit i of a + b (carry in 0): the majority, bit by bit from the bottom.
    fn carry_out(a: u32, b: u32, i: u8) -> u8 {
        var c : u32 = 0;
        var j : u8 = 0;
        while (j <= i && j < MAX_BITS) {
            const x = (a >> j) & 1;
            const y = (b >> j) & 1;
            c = (x & y) | (x & c) | (y & c);
            j = j + 1;
        }
        return c as u8;
    }

    // Bit i of a + b.
    fn sum_bit(a: u32, b: u32, i: u8) -> u8 {
        var cin : u32 = 0;
        if (i > 0) {
            cin = carry_out(a, b, i - 1) as u32;
        }
        return (((a >> i) ^ (b >> i) ^ cin) & 1) as u8;
    }

    // a + b over n bits, the carry out of the top bit included, as one number.
    fn sum_value(a: u32, b: u32, n: u8) -> f64 {
        var v : f64 = 0.0;
        var w : f64 = 1.0;
        var i : u8 = 0;
        while (i < n) {
            v = v + w * (sum_bit(a, b, i) as f64);
            w = w * 2.0;
            i = i + 1;
        }
        if (n > 0) {
            v = v + w * (carry_out(a, b, n - 1) as f64);
        }
        return v;
    }

    // 1 when bit i generates a carry, 2 when it propagates one, 0 when it kills it.
    fn bit_role(a: u32, b: u32, i: u8) -> u8 {
        const x = (a >> i) & 1;
        const y = (b >> i) & 1;
        if (x == 1 && y == 1) {
            return 1;
        }
        if ((x ^ y) == 1) {
            return 2;
        }
        return 0;
    }

    // The longest run of consecutive bits whose carry out is 1, over bits 0..n-1: how far the
    // slowest carry of this particular sum travels.
    fn carry_run(a: u32, b: u32, n: u8) -> u8 {
        var best : u8 = 0;
        var cur : u8 = 0;
        var i : u8 = 0;
        while (i < n) {
            if (carry_out(a, b, i) == 1) {
                cur = cur + 1;
                if (cur > best) {
                    best = cur;
                }
            } else {
                cur = 0;
            }
            i = i + 1;
        }
        return best;
    }

    // A carry recomputed by a LUT in every bit: a LUT and a route per bit.
    fn ripple_ps(n: u8, lut_ps: u16, route_ps: u16) -> u32 {
        return (n as u32) * ((lut_ps as u32) + (route_ps as u32));
    }

    // The dedicated chain: one LUT and one route into it, then one hop per bit.
    fn chain_ps(n: u8, lut_ps: u16, route_ps: u16, hop_ps: u16) -> u32 {
        return (lut_ps as u32) + (route_ps as u32) + (n as u32) * (hop_ps as u32);
    }

    // CARRY4 blocks (one per slice) an n-bit chain occupies.
    fn carry4_blocks(n: u8) -> u8 {
        return (n + CARRY4_BITS - 1) / CARRY4_BITS;
    }

    // ---- Prefix networks -------------------------------------------------------------------

    // log2 of a power of two n (2..32).
    fn depth_of(n: u8) -> u8 {
        var d : u8 = 0;
        var m : u8 = n;
        while (m > 1) {
            m = m / 2;
            d = d + 1;
        }
        return d;
    }

    // Logic levels of a network over n columns.
    fn levels(net: u8, n: u8) -> u8 {
        const d = depth_of(n);
        if (net == NET_RIPPLE) {
            return n - 1;
        }
        if (net == NET_BRENT_KUNG) {
            return 2 * d - 1;
        }
        return d;
    }

    // The column that column i combines with at one level, or -1.
    fn src(net: u8, n: u8, i: u8, level: u8) -> i16 {
        const d = depth_of(n);
        const ii = i as i16;
        if (net == NET_RIPPLE) {
            if (i >= 1 && level == i - 1) {
                return ii - 1;
            }
            return -1;
        }
        if (net == NET_SKLANSKY) {
            if (level < d && ((i >> level) & 1) == 1) {
                return (((i >> level) << level) as i16) - 1;
            }
            return -1;
        }
        if (net == NET_KOGGE_STONE) {
            if (level < d && (ii >= ((1 as i16) << level))) {
                return ii - ((1 as i16) << level);
            }
            return -1;
        }
        if (level < d) {
            const span = (1 as i16) << level;
            if (@rem(ii + 1, span * 2) == 0) {
                return ii - span;
            }
            return -1;
        }
        if (level - d + 2 > d) {
            return -1;
        }
        const k = d - 2 - (level - d);
        const half = (1 as i16) << k;
        if (@rem(ii + 1, half * 2) == half && ii >= 3 * half - 1) {
            return ii - half;
        }
        return -1;
    }

    // Prefix cells (black dots) the network uses: every (column, level) with a source.
    fn cells(net: u8, n: u8) -> u16 {
        var count : u16 = 0;
        var level : u8 = 0;
        const top = levels(net, n);
        while (level < top) {
            var i : u8 = 0;
            while (i < n) {
                if (src(net, n, i, level) >= 0) {
                    count = count + 1;
                }
                i = i + 1;
            }
            level = level + 1;
        }
        return count;
    }

    // The most cells one column feeds at a single level.
    fn max_fanout(net: u8, n: u8) -> u8 {
        var best : u8 = 0;
        var level : u8 = 0;
        const top = levels(net, n);
        while (level < top) {
            var j : u8 = 0;
            while (j < n) {
                var fan : u8 = 0;
                var i : u8 = 0;
                while (i < n) {
                    if (src(net, n, i, level) == (j as i16)) {
                        fan = fan + 1;
                    }
                    i = i + 1;
                }
                if (fan > best) {
                    best = fan;
                }
                j = j + 1;
            }
            level = level + 1;
        }
        return best;
    }

    // Replays the network on spans: column i starts as [i..i]; joining i with s is legal only
    // when s ends right below i's span, and leaves i spanning down to s's low end. True when
    // every join was legal and every column ends spanning [0..i].
    fn covers(net: u8, n: u8) -> bool {
        var lo : [32]i16 = [0; 32];
        var nxt : [32]i16 = [0; 32];
        var i : u8 = 0;
        while (i < n) {
            lo[i] = i as i16;
            i = i + 1;
        }
        var level : u8 = 0;
        const top = levels(net, n);
        while (level < top) {
            var j : u8 = 0;
            while (j < n) {
                nxt[j] = lo[j];
                const s = src(net, n, j, level);
                if (s >= 0) {
                    if (lo[j] != s + 1) {
                        return false;
                    }
                    nxt[j] = lo[s as u8];
                }
                j = j + 1;
            }
            var c : u8 = 0;
            while (c < n) {
                lo[c] = nxt[c];
                c = c + 1;
            }
            level = level + 1;
        }
        var k : u8 = 0;
        while (k < n) {
            if (lo[k] != 0) {
                return false;
            }
            k = k + 1;
        }
        return true;
    }

    // ---- Carry-save trees ------------------------------------------------------------------

    // The Dadda height d(j), j >= 1: d(1) = 2, d(j+1) = floor(3 d(j) / 2).
    fn dadda(j: u8) -> u16 {
        var d : u16 = DADDA_FIRST;
        var k : u8 = 1;
        while (k < j) {
            d = d * 3 / 2;
            k = k + 1;
        }
        return d;
    }

    // Layers of 3:2 counters that reduce k operands to two: the j with d(j) < k <= d(j+1).
    fn csa_levels(k: u16) -> u8 {
        if (k <= DADDA_FIRST) {
            return 0;
        }
        var j : u8 = 1;
        while (dadda(j + 1) < k) {
            j = j + 1;
        }
        return j;
    }

    // One Wallace layer: every group of three rows becomes two, the rest pass through.
    fn wallace_next(k: u16) -> u16 {
        return 2 * (k / 3) + k % 3;
    }

    // Wallace layers until two rows are left.
    fn wallace_levels(k: u16) -> u8 {
        var rows : u16 = k;
        var n : u8 = 0;
        while (rows > 2) {
            rows = wallace_next(rows);
            n = n + 1;
        }
        return n;
    }

    // The sum word of a 3:2 counter: one full adder per bit, no carry between bits.
    fn csa_sum(a: u16, b: u16, c: u16) -> u32 {
        return ((a as u32) ^ (b as u32)) ^ (c as u32);
    }

    // The carry word of a 3:2 counter, already shifted to the next bit.
    fn csa_carry(a: u16, b: u16, c: u16) -> u32 {
        const x = a as u32;
        const y = b as u32;
        const z = c as u32;
        return ((x & y) | (x & z) | (y & z)) << 1;
    }

    // What the two words of a 3:2 counter add up to: a + b + c.
    fn csa_total(a: u16, b: u16, c: u16) -> u32 {
        return csa_sum(a, b, c) + csa_carry(a, b, c);
    }

    // Full-adder delays to add k n-bit numbers: k - 1 carry-propagate adders in a row
    // (each n deep, no overlap) against a carry-save tree and one final adder.
    fn chain_fa_delays(k: u16, n: u8) -> u32 {
        return ((k as u32) - 1) * (n as u32);
    }

    fn tree_fa_delays(k: u16, n: u8) -> u32 {
        return (csa_levels(k) as u32) + (n as u32);
    }

    // Full adders the carry-save layers use: each removes one operand of n bits.
    fn csa_adders(k: u16, n: u8) -> u32 {
        if (k <= 2) {
            return 0;
        }
        return ((k as u32) - 2) * (n as u32);
    }

    // Every k from 3 to top: the Wallace count equals the Dadda count.
    fn wallace_is_dadda(top: u16) -> bool {
        var k : u16 = 2;
        while (k <= top) {
            if (wallace_levels(k) != csa_levels(k)) {
                return false;
            }
            k = k + 1;
        }
        return true;
    }

    // ---- Tests -----------------------------------------------------------------------------

    test "the sum bits are the sum" {
        assert(sum_bit(100, 27, 0) == 1);
        assert(sum_bit(100, 27, 6) == 1);
        assert(sum_bit(100, 27, 7) == 0);
        assert(sum_bit(255, 1, 0) == 0);
        assert(sum_bit(255, 1, 8) == 1);
        assert(carry_out(127, 1, 6) == 1);
        assert(carry_out(127, 1, 7) == 0);
        assert(sum_value(100, 27, 8) == 127.0);
        assert(sum_value(4294967295, 1, 32) == 4294967296.0);
    }

    test "a carry runs as far as the bits propagate it" {
        assert(carry_run(127, 1, 8) == 7);
        assert(carry_run(255, 1, 8) == 8);
        assert(carry_run(85, 170, 8) == 0);
        assert(carry_run(3855, 241, 12) == 12);
        assert(bit_role(5, 3, 0) == 1);
        assert(bit_role(5, 3, 1) == 2);
        assert(bit_role(5, 3, 3) == 0);
    }

    test "the chain beats the LUT ripple and fills CARRY4 blocks" {
        assert(ripple_ps(32, 120, 300) == 13440);
        assert(chain_ps(32, 120, 300, 30) == 1380);
        assert(carry4_blocks(32) == 8);
        assert(carry4_blocks(33) == 9);
        assert(carry4_blocks(1) == 1);
    }

    test "every prefix network computes every carry" {
        var n : u8 = 2;
        while (n <= 32) {
            assert(covers(NET_RIPPLE, n));
            assert(covers(NET_SKLANSKY, n));
            assert(covers(NET_KOGGE_STONE, n));
            assert(covers(NET_BRENT_KUNG, n));
            n = n * 2;
        }
    }

    test "cell counts are the closed forms" {
        assert(cells(NET_RIPPLE, 16) == 15);
        assert(cells(NET_SKLANSKY, 16) == 32);
        assert(cells(NET_KOGGE_STONE, 16) == 49);
        assert(cells(NET_BRENT_KUNG, 16) == 26);
        assert(cells(NET_KOGGE_STONE, 32) == 129);
        assert(cells(NET_BRENT_KUNG, 32) == 57);
        assert(cells(NET_SKLANSKY, 8) == 12);
        assert(cells(NET_BRENT_KUNG, 8) == 11);
    }

    test "levels trade against cells and fanout" {
        assert(levels(NET_RIPPLE, 32) == 31);
        assert(levels(NET_SKLANSKY, 32) == 5);
        assert(levels(NET_KOGGE_STONE, 32) == 5);
        assert(levels(NET_BRENT_KUNG, 32) == 9);
        assert(max_fanout(NET_SKLANSKY, 32) == 16);
        assert(max_fanout(NET_KOGGE_STONE, 32) == 1);
        assert(max_fanout(NET_BRENT_KUNG, 32) == 1);
        assert(src(NET_KOGGE_STONE, 8, 5, 2) == 1);
        assert(src(NET_SKLANSKY, 8, 6, 1) == 5);
        assert(src(NET_BRENT_KUNG, 8, 5, 3) == 3);
    }

    test "the Dadda heights and the carry-save levels" {
        assert(dadda(1) == 2);
        assert(dadda(5) == 9);
        assert(dadda(10) == 63);
        assert(csa_levels(2) == 0);
        assert(csa_levels(3) == 1);
        assert(csa_levels(4) == 2);
        assert(csa_levels(9) == 4);
        assert(csa_levels(10) == 5);
        assert(csa_levels(64) == 10);
        assert(wallace_next(28) == 19);
        assert(wallace_is_dadda(300));
    }

    test "a 3:2 counter keeps the sum" {
        assert(csa_sum(11, 6, 13) == 0);
        assert(csa_carry(11, 6, 13) == 30);
        assert(csa_total(200, 100, 50) == 350);
        assert(csa_sum(11, 6, 13) + csa_carry(11, 6, 13) == 30);
        assert(csa_sum(65535, 65535, 65535) + csa_carry(65535, 65535, 65535) == 196605);
        assert(tree_fa_delays(16, 16) == 22);
        assert(chain_fa_delays(16, 16) == 240);
        assert(csa_adders(16, 16) == 224);
    }

    test "VERSION says what the header says" {
        assert(VERSION == 1);
        assert(carry4_blocks(MAX_BITS) == 8);
        assert(depth_of(MAX_BITS) == 5);
    }
}
// phi^2 + 1/phi^2 = 3 | TRINITY
All lessons
Module 1 · Adding numbers
Why addition is slow: the carry that walks up the word, the dedicated chain in every slice, prefix networks and carry-save trees.
Module 2 · Multiplying
A product is a sum of shifted copies; Booth recoding halves them, and the DSP48E1 slice does the rest in one block.
Module 3 · Fixed point
Where the binary point sits, what rounding does to a value and to its average, and what each bit of a quantizer buys.
Module 4 · Functions in hardware
Sine, cosine, angle and length from shifts and adds, and when a table is the better answer.
Module 5 · Signals and sampling
What sampling does to a frequency, how an oscillator is built from an adder, and what a DFT bin measures.
Module 6 · FIR filters
The moving average, a windowed-sinc design with integer taps, and folding the taps onto DSP slices.
Module 7 · Multirate
Lowering the sample rate without folding noise in: decimation, the CIC filter and the polyphase form.
Module 8 · The FFT
N log N instead of N^2: butterflies, the bit-reversed input order and the bits each stage adds.
Module 9 · On the bench
From the arithmetic to the board: a correlator from the modem spec, a budget of slices and timing, and the capstone filter.