Positional encoding
You will learn
How sines and cosines at falling frequencies give every position its own vector, and why a shift is a turn.
Attention treats its input as a set, so the order of the words has to be added to them. The sinusoidal encoding gives each position d numbers: the sin and cos of the position times a frequency that falls by 10000^(2/d) from pair to pair. With d = 8 the four pairs turn by 1, 0.1, 0.01 and 0.001 radians per position, like the hands of four clocks: position 5 reads -0.959, 0.284 in its fast pair and 0.005, 1.000 in its slow one. Each pair has length 1, and a shift by k positions turns every pair by its own fixed angle. The spec positional_encoding.t27 computes every value.
Try it
Step from position 0 to 1 and watch which clock moves; then jump to 37 and find the pair that still points up.
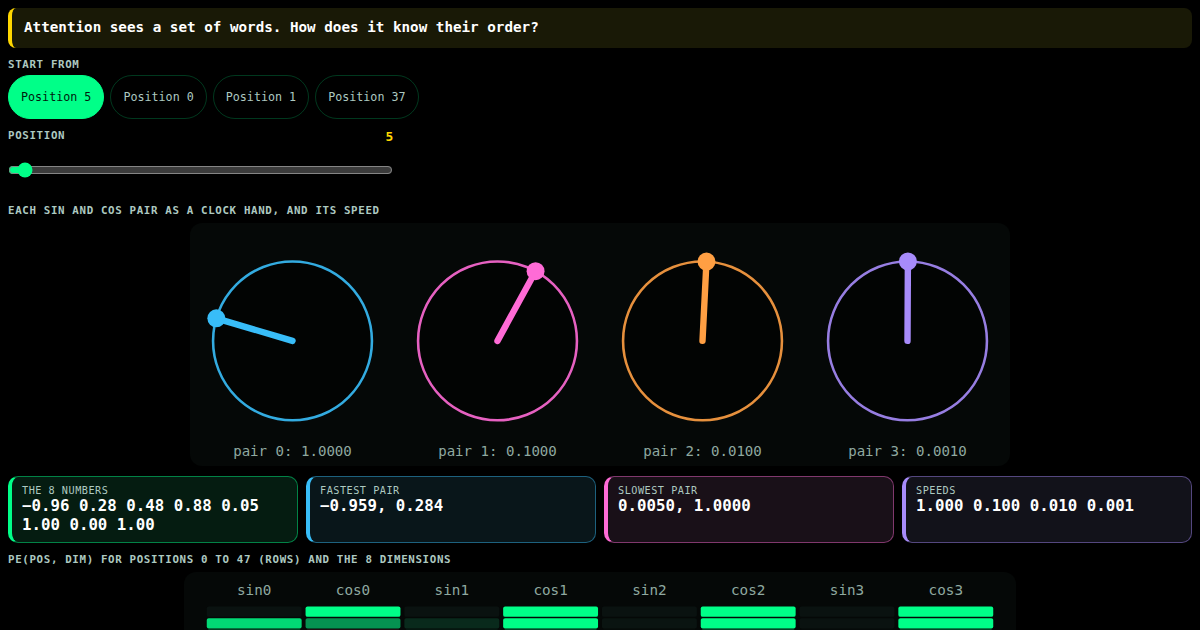
Every position gets 8 numbers, sines and cosines at frequencies falling by 10 per pair. Drag the position: the fast clock spins, the slow ones barely move, and the stripes show all 48 rows.
specs/ml/transformer/positional_encoding.t27
// SPDX-License-Identifier: Apache-2.0
// t27/specs/
// Uses sin/cos at different frequencies for each dimension | φ² + 1/φ² = 3 | TRINITY

// #8980: forward read an undeclared `d_model`, called `math::pow` / `math::sin` /
// `math::cos`, computed each encoding into a local and dropped it, and grew the
// frequency with the dimension where Vaswani et al. (2017) shrink it. It now
// writes the sinusoidal encoding
//   PE(pos, 2i) = sin(pos / 10000^(2i / d)),  PE(pos, 2i + 1) = cos(pos / 10000^(2i / d))
// for each position into a positions x d_model buffer.

module PositionalEnc;
    use base::types;
    use math::constants;

    // ═══════════════════════════════════════════════════════════
    // 1. Constants
    // ═══════════════════════════════════════════════════════════

    const DEFAULT_MAX_LEN : u32 = 2048;

    // ═══════════════════════════════════════════════════════════
    // 2. Types
    // ═══════════════════════════════════════════════════════════

    pub const PosEncConfig = struct {
        d_model : u32,
        max_len : u32,
    };

    // ═══════════════════════════════════════════════════════════
    // 3. Core Functions
    // ═══════════════════════════════════════════════════════════

    // 1 / 10000^(2i / d) = exp(-(2i / d) ln 10000)
    fn inv_freq(pair: u32, d_model: u32) -> f32 {
        return exp(-(@as(f32, @floatFromInt(2 * pair)) / @as(f32, @floatFromInt(d_model))) * log(@as(f32, 10000.0)));
    }

    fn forward(positions: []const u32, config: PosEncConfig, out: []f32) -> void {
        var p : usize = 0;
        while (p < positions.len) {
            const pos : f32 = @as(f32, @floatFromInt(positions[p]));
            var dim : u32 = 0;
            while (dim < config.d_model) {
                const angle = pos * inv_freq(dim / 2, config.d_model);
                if (dim % 2 == 0) {
                    out[p * config.d_model + dim] = sin(angle);
                } else {
                    out[p * config.d_model + dim] = cos(angle);
                }
                dim = dim + 1;
            }
            p = p + 1;
        }
    }

    // PE(pos, dim) for d_model 8
    fn pe(pos: u32, dim: usize) -> f32 {
        const positions : [1]u32 = [pos];
        var out : [8]f32 = [9.0] ** 8;
        forward(&positions, PosEncConfig{ .d_model = 8, .max_len = DEFAULT_MAX_LEN }, &out);
        return out[dim];
    }

    // ═══════════════════════════════════════════════════════════
    // TDD: Tests (from .tri behaviors)
    // ═══════════════════════════════════════════════════════════

    // pos 1, d 8: dims 0/1 use frequency 1, dims 2/3 use 1/10 (10000^(2/8) = 10)
    test forward_basic_case
        given s0 = pe(1, 0)
        when s2 = pe(1, 2)
        then @abs(s0 - 0.8414710) < 0.000001 and @abs(pe(1, 1) - 0.5403023) < 0.000001 and @abs(s2 - 0.0998334) < 0.000001 and @abs(pe(1, 3) - 0.9950042) < 0.000001

    // Position 0 encodes as (0, 1, 0, 1, ...)
    test forward_simple
        given s = pe(0, 6)
        when c = pe(0, 7)
        then s == 0.0 and c == 1.0

    // Each sin/cos pair lies on the unit circle
    test forward_pairs_are_unit_vectors
        given p = pe(37, 2) * pe(37, 2) + pe(37, 3) * pe(37, 3)
        then @abs(p - 1.0) < 0.000001

    invariant positional_encoding_max_len_is_positive
        assert DEFAULT_MAX_LEN > 0
All lessons
Module 1 · One neuron
A neuron sums its inputs and bends the sum: ReLU, the sigmoid and tanh, and where each one stops passing a gradient back.
Module 2 · New bends
The smooth curves of current models: GELU with its dip, Swish with its knob, and ELU with a floor instead of a cliff.
Module 3 · A layer
What sits around the neurons: softmax turns scores into a choice, an embedding turns a word into numbers, dropout switches units off.
Module 4 · Pictures
Reading a picture in patches: a window averaged over its patch, max pooling, and batch normalisation of features on different scales.
Module 5 · The error
How wrong a guess is, as one number: mean squared error, cross-entropy for probabilities, and the Huber loss for outliers.
Module 6 · Downhill
Walking down the loss: gradient descent with momentum, RMSProp that ignores the gradient's size, and Adam that combines them.
Module 7 · Learning
Where the gradients come from and what they achieve: backpropagation through a layer, a network that learns XOR, and LAMB for large batches.
Module 8 · Memory and attention
Networks that read a sequence: a recurrent cell and its fading echo, the gates of an LSTM, and attention over every position at once.
Module 9 · The transformer and the reward
The parts of a transformer and of an agent: positions as clocks, one encoder block, and PPO, which learns from reward without lurching.