LSTM gates
You will learn
How the forget, input and output gates of an LSTM decide what the cell keeps, writes and shows.
An LSTM cell keeps a separate memory c and three gates, each a sigmoid between 0 and 1: forget scales the old memory, input lets in new content g, and output decides how much of the memory to show. c' = f c + i g and h' = o tanh(c'). In the spec's fixture every weight is 0, so each gate is the sigmoid of its bias: with the forget gate at 0.9975 and the input gate at 0.0025, a memory of 1 comes out as 0.9975, and the output is 0.7587. Because c passes through with only a multiply by f, its gradient survives many steps too. The spec lstm_single.t27 computes the cell.
Try it
Load Remember and then Forget and compare the new memory; then write with the input gate open.
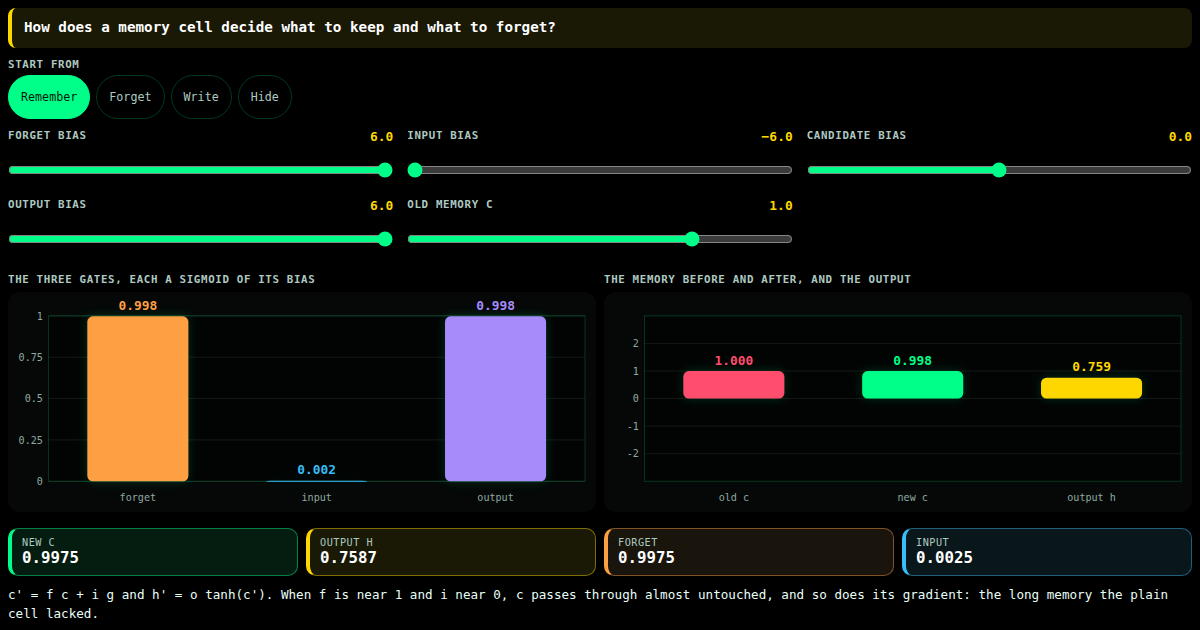
Set the biases of the forget, input and output gates and the old memory: the new memory is forget x old + input x candidate, and the output shows tanh of it through the output gate.
specs/ml/recurrent/lstm_single.t27
// SPDX-License-Identifier: Apache-2.0
// t27/specs/
// LSTM solves vanishing gradient problem | φ² + 1/φ² = 3 | TRINITY

// #8980: called `@sigmoid` and `@tanh`, which Zig does not have; each gate weight
// was one number per INPUT, indexed `i % hidden_size`, so it was not an LSTM; and
// every test asserted `true`. Now each gate has its own matrices, W_x
// (hidden x input) and W_h (hidden x hidden), and a bias:
//   i = s(z_i), f = s(z_f), g = tanh(z_g), o = s(z_o),  z = W_x x + W_h h + b
//   c' = f c + i g,  h' = o tanh(c')
// backward gives every gradient of one step, and the tests check it against finite
// differences.

module LstmCell;
    use base::types;
    use math::constants;

    // ═══════════════════════════════════════════════════════════
    // 1. Constants
    // ═══════════════════════════════════════════════════════════

    const FORGET_BIAS_INIT : f32 = 1.0;

    // ═══════════════════════════════════════════════════════════
    // 2. Types
    // ═══════════════════════════════════════════════════════════

    pub const LSTMConfig = struct {
        input_size : u32,
        hidden_size : u32,
    };

    pub const LSTMState = struct {
        h : []f32,
        c : []f32,
    };

    pub const LSTMWeights = struct {
        W_ii : []f32,
        W_hi : []f32,
        b_i : []f32,
        W_if : []f32,
        W_hf : []f32,
        b_f : []f32,
        W_ig : []f32,
        W_hg : []f32,
        b_g : []f32,
        W_io : []f32,
        W_ho : []f32,
        b_o : []f32,
    };

    // ═══════════════════════════════════════════════════════════
    // 3. Core Functions
    // ═══════════════════════════════════════════════════════════

    fn sigmoid(z: f32) -> f32 {
        return 1.0 / (1.0 + exp(-z));
    }

    // Pre-activation of one gate for hidden unit u: W_x[u] . x + W_h[u] . h + b[u]
    fn pre(w_x: []const f32, w_h: []const f32, b: []const f32, x: []const f32, h: []const f32, u: usize, config: LSTMConfig) -> f32 {
        var z : f32 = b[u];
        var j : usize = 0;
        while (j < config.input_size) {
            z = z + w_x[u * config.input_size + j] * x[j];
            j = j + 1;
        }
        var k : usize = 0;
        while (k < config.hidden_size) {
            z = z + w_h[u * config.hidden_size + k] * h[k];
            k = k + 1;
        }
        return z;
    }

    fn forward(input: []const f32, state: LSTMState, weights: LSTMWeights, output_state: LSTMState, config: LSTMConfig) -> void {
        var u : usize = 0;
        while (u < config.hidden_size) {
            const ig = sigmoid(pre(weights.W_ii, weights.W_hi, weights.b_i, input, state.h, u, config));
            const fg = sigmoid(pre(weights.W_if, weights.W_hf, weights.b_f, input, state.h, u, config));
            const gg = tanh(pre(weights.W_ig, weights.W_hg, weights.b_g, input, state.h, u, config));
            const og = sigmoid(pre(weights.W_io, weights.W_ho, weights.b_o, input, state.h, u, config));
            output_state.c[u] = fg * state.c[u] + ig * gg;
            output_state.h[u] = og * tanh(output_state.c[u]);
            u = u + 1;
        }
    }

    // Adds dz * (x, h, 1) into one gate's weight gradients, and dz * W into grad_input / grad_state.h
    fn spread(dz: f32, w_x: []const f32, w_h: []const f32, gw_x: []f32, gw_h: []f32, gb: []f32, x: []const f32, h: []const f32, u: usize, config: LSTMConfig, grad_input: []f32, grad_h: []f32) -> void {
        var j : usize = 0;
        while (j < config.input_size) {
            gw_x[u * config.input_size + j] = gw_x[u * config.input_size + j] + dz * x[j];
            grad_input[j] = grad_input[j] + dz * w_x[u * config.input_size + j];
            j = j + 1;
        }
        var k : usize = 0;
        while (k < config.hidden_size) {
            gw_h[u * config.hidden_size + k] = gw_h[u * config.hidden_size + k] + dz * h[k];
            grad_h[k] = grad_h[k] + dz * w_h[u * config.hidden_size + k];
            k = k + 1;
        }
        gb[u] = gb[u] + dz;
    }

    // One step back. grad_output = dL/dh', grad_cell = dL/dc' from later steps. Writes
    // dL/dx, dL/dh, dL/dc and ADDS the weight gradients into grad_weights.
    //   do = dh' tanh(c');  dc = dh' o (1 - tanh^2 c') + grad_cell
    //   dz_o = do o (1 - o), dz_f = dc c f (1 - f), dz_i = dc g i (1 - i), dz_g = dc i (1 - g^2)
    //   dL/dc = dc f
    fn backward(grad_output: []const f32, grad_cell: []const f32, input: []const f32, state: LSTMState, weights: LSTMWeights, config: LSTMConfig, grad_input: []f32, grad_state: LSTMState, grad_weights: LSTMWeights) -> void {
        var j : usize = 0;
        while (j < config.input_size) {
            grad_input[j] = 0.0;
            j = j + 1;
        }
        var u : usize = 0;
        while (u < config.hidden_size) {
            grad_state.h[u] = 0.0;
            u = u + 1;
        }
        u = 0;
        while (u < config.hidden_size) {
            const ig = sigmoid(pre(weights.W_ii, weights.W_hi, weights.b_i, input, state.h, u, config));
            const fg = sigmoid(pre(weights.W_if, weights.W_hf, weights.b_f, input, state.h, u, config));
            const gg = tanh(pre(weights.W_ig, weights.W_hg, weights.b_g, input, state.h, u, config));
            const og = sigmoid(pre(weights.W_io, weights.W_ho, weights.b_o, input, state.h, u, config));
            const c_new = fg * state.c[u] + ig * gg;
            const tc = tanh(c_new);
            const dc = grad_output[u] * og * (1.0 - tc * tc) + grad_cell[u];
            const dz_o = grad_output[u] * tc * og * (1.0 - og);
            const dz_f = dc * state.c[u] * fg * (1.0 - fg);
            const dz_i = dc * gg * ig * (1.0 - ig);
            const dz_g = dc * ig * (1.0 - gg * gg);
            grad_state.c[u] = dc * fg;
            spread(dz_i, weights.W_ii, weights.W_hi, grad_weights.W_ii, grad_weights.W_hi, grad_weights.b_i, input, state.h, u, config, grad_input, grad_state.h);
            spread(dz_f, weights.W_if, weights.W_hf, grad_weights.W_if, grad_weights.W_hf, grad_weights.b_f, input, state.h, u, config, grad_input, grad_state.h);
            spread(dz_g, weights.W_ig, weights.W_hg, grad_weights.W_ig, grad_weights.W_hg, grad_weights.b_g, input, state.h, u, config, grad_input, grad_state.h);
            spread(dz_o, weights.W_io, weights.W_ho, grad_weights.W_io, grad_weights.W_ho, grad_weights.b_o, input, state.h, u, config, grad_input, grad_state.h);
            u = u + 1;
        }
    }

    // The fixture: input 3, hidden 2. All 48 weights live in one buffer, per gate
    // W_x (6), W_h (4), b (2), in the gate order i, f, g, o.
    fn cfg() -> LSTMConfig {
        return LSTMConfig{ .input_size = 3, .hidden_size = 2 };
    }

    fn weights_of(w: []f32) -> LSTMWeights {
        return LSTMWeights{
            .W_ii = w[0..6], .W_hi = w[6..10], .b_i = w[10..12],
            .W_if = w[12..18], .W_hf = w[18..22], .b_f = w[22..24],
            .W_ig = w[24..30], .W_hg = w[30..34], .b_g = w[34..36],
            .W_io = w[36..42], .W_ho = w[42..46], .b_o = w[46..48],
        };
    }

    // Deterministic weights in [-0.5, 0.5]; the forget biases start at FORGET_BIAS_INIT
    fn fill(w: []f32) -> void {
        var k : usize = 0;
        while (k < 48) {
            w[k] = @as(f32, @floatFromInt((k * 7 + 3) % 11)) / 10.0 - 0.5;
            k = k + 1;
        }
        w[22] = FORGET_BIAS_INIT;
        w[23] = FORGET_BIAS_INIT;
    }

    // L = 0.5 h'_0 - 0.3 h'_1 + 0.2 c'_0 + 0.1 c'_1 after one step, with one input, one h or
    // one c entry moved by `delta` (which: 0 = none, 1 + j = x_j, 4 + k = h_k, 6 + k = c_k,
    // 8 = b_f[1])
    fn loss(which: usize, delta: f32) -> f32 {
        var w : [48]f32 = undefined;
        fill(&w);
        var x : [3]f32 = [1.0, 2.0, 3.0];
        var h : [2]f32 = [0.1, 0.2];
        var c : [2]f32 = [0.3, 0.4];
        if (which >= 1 and which <= 3) {
            x[which - 1] = x[which - 1] + delta;
        }
        if (which >= 4 and which <= 5) {
            h[which - 4] = h[which - 4] + delta;
        }
        if (which >= 6 and which <= 7) {
            c[which - 6] = c[which - 6] + delta;
        }
        if (which == 8) {
            w[23] = w[23] + delta;
        }
        var h_out : [2]f32 = [0.0] ** 2;
        var c_out : [2]f32 = [0.0] ** 2;
        forward(&x, LSTMState{ .h = &h, .c = &c }, weights_of(&w), LSTMState{ .h = &h_out, .c = &c_out }, cfg());
        return 0.5 * h_out[0] - 0.3 * h_out[1] + 0.2 * c_out[0] + 0.1 * c_out[1];
    }

    // The analytic gradient of that loss, same `which` numbering
    fn grad(which: usize) -> f32 {
        var w : [48]f32 = undefined;
        fill(&w);
        const x : [3]f32 = [1.0, 2.0, 3.0];
        var h : [2]f32 = [0.1, 0.2];
        var c : [2]f32 = [0.3, 0.4];
        const grad_output : [2]f32 = [0.5, -0.3];
        const grad_cell : [2]f32 = [0.2, 0.1];
        var gx : [3]f32 = [0.0] ** 3;
        var gh : [2]f32 = [0.0] ** 2;
        var gc : [2]f32 = [0.0] ** 2;
        var gw : [48]f32 = [0.0] ** 48;
        backward(&grad_output, &grad_cell, &x, LSTMState{ .h = &h, .c = &c }, weights_of(&w), cfg(), &gx, LSTMState{ .h = &gh, .c = &gc }, weights_of(&gw));
        if (which >= 1 and which <= 3) {
            return gx[which - 1];
        }
        if (which >= 4 and which <= 5) {
            return gh[which - 4];
        }
        if (which >= 6 and which <= 7) {
            return gc[which - 6];
        }
        return gw[23];
    }

    // Sum of |every gradient| when grad_output and grad_cell are both 0
    fn zero_upstream_total() -> f32 {
        var w : [48]f32 = undefined;
        fill(&w);
        const x : [3]f32 = [1.0, 2.0, 3.0];
        var h : [2]f32 = [0.1, 0.2];
        var c : [2]f32 = [0.3, 0.4];
        const zeros : [2]f32 = [0.0, 0.0];
        var gx : [3]f32 = [0.0] ** 3;
        var gh : [2]f32 = [0.0] ** 2;
        var gc : [2]f32 = [0.0] ** 2;
        var gw : [48]f32 = [0.0] ** 48;
        backward(&zeros, &zeros, &x, LSTMState{ .h = &h, .c = &c }, weights_of(&w), cfg(), &gx, LSTMState{ .h = &gh, .c = &gc }, weights_of(&gw));
        var total : f32 = @abs(gx[0]) + @abs(gx[1]) + @abs(gx[2]) + @abs(gh[0]) + @abs(gh[1]) + @abs(gc[0]) + @abs(gc[1]);
        var k : usize = 0;
        while (k < 48) {
            total = total + @abs(gw[k]);
            k = k + 1;
        }
        return total;
    }

    fn slope(which: usize) -> f32 {
        return (loss(which, 0.001) - loss(which, -0.001)) / 0.002;
    }

    // which: 0 = h'_0, 1 = c'_0 for a 1-unit cell with every weight 0 and the given biases
    fn bias_only(b_i: f32, b_f: f32, b_g: f32, b_o: f32, c_prev: f32, which: u8) -> f32 {
        var w : [48]f32 = [0.0] ** 48;
        w[10] = b_i;
        w[22] = b_f;
        w[34] = b_g;
        w[46] = b_o;
        const x : [3]f32 = [1.0, 2.0, 3.0];
        var h : [2]f32 = [0.0, 0.0];
        var c : [2]f32 = [c_prev, 0.0];
        var h_out : [2]f32 = [9.0] ** 2;
        var c_out : [2]f32 = [9.0] ** 2;
        forward(&x, LSTMState{ .h = &h, .c = &c }, weights_of(&w), LSTMState{ .h = &h_out, .c = &c_out }, cfg());
        if (which == 0) {
            return h_out[0];
        }
        return c_out[0];
    }

    fn valid_input() -> usize {
        return cfg().input_size;
    }

    // ═══════════════════════════════════════════════════════════
    // TDD: Tests (from .tri behaviors)
    // ═══════════════════════════════════════════════════════════

    // All weights 0: every gate is s(0) = 0.5 or tanh(0) = 0, so c' = 0.5 c and h' = 0.5 tanh(c')
    test forward_basic_case
        given c_new = bias_only(0.0, 0.0, 0.0, 0.0, 0.8, 1)
        when h_new = bias_only(0.0, 0.0, 0.0, 0.0, 0.8, 0)
        then @abs(c_new - 0.4) < 0.000001 and @abs(h_new - 0.5 * tanh(c_new)) < 0.000001 and @abs(h_new - 0.1899745) < 0.000001

    // A closed forget gate (b_f = -30) erases the old cell; an open one (b_f = 30) keeps it
    test forward_basic_lstm
        given erased = bias_only(0.0, -30.0, 0.0, 0.0, 0.8, 1)
        when kept = bias_only(-30.0, 30.0, 0.0, 0.0, 0.8, 1)
        then @abs(erased) < 0.000001 and @abs(kept - 0.8) < 0.000001

    // A closed input gate and forget gate leave c' = 0, so h' = 0 whatever the output gate does
    test forward_with_empty_input
        given h_new = bias_only(-30.0, -30.0, 1.0, 30.0, 0.8, 0)
        then @abs(h_new) < 0.000001

    // dL/dx_j against central differences
    test backward_basic_case
        given g0 = grad(1)
        when g2 = grad(3)
        then @abs(g0 - slope(1)) < 0.0005 and @abs(grad(2) - slope(2)) < 0.0005 and @abs(g2 - slope(3)) < 0.0005

    // dL/dh_k, dL/dc_k and dL/db_f[1] against central differences
    test backward_basic_lstm
        given gh0 = grad(4)
        when gc1 = grad(7)
        then @abs(gh0 - slope(4)) < 0.0005 and @abs(grad(5) - slope(5)) < 0.0005 and @abs(grad(6) - slope(6)) < 0.0005 and @abs(gc1 - slope(7)) < 0.0005 and @abs(grad(8) - slope(8)) < 0.0005

    // With no upstream gradient nothing flows back
    test backward_with_empty_grad
        given total = zero_upstream_total()
        then total == 0.0 and @abs(grad(1)) > 0.0

    // ═══════════════════════════════════════════════════════════
    // TDD: Invariants (from .tri constraints)
    // ═══════════════════════════════════════════════════════════

    // input.size() == config.input_size
    invariant lstm_cell_constraint_0
        assert valid_input() == 3

    // state.h.size() == config.hidden_size
    invariant lstm_cell_constraint_1
        assert cfg().hidden_size == 2

    // state.c.size() == config.hidden_size; the forget bias starts open
    invariant lstm_cell_constraint_2
        assert FORGET_BIAS_INIT > 0.0
All lessons
Module 1 · One neuron
A neuron sums its inputs and bends the sum: ReLU, the sigmoid and tanh, and where each one stops passing a gradient back.
Module 2 · New bends
The smooth curves of current models: GELU with its dip, Swish with its knob, and ELU with a floor instead of a cliff.
Module 3 · A layer
What sits around the neurons: softmax turns scores into a choice, an embedding turns a word into numbers, dropout switches units off.
Module 4 · Pictures
Reading a picture in patches: a window averaged over its patch, max pooling, and batch normalisation of features on different scales.
Module 5 · The error
How wrong a guess is, as one number: mean squared error, cross-entropy for probabilities, and the Huber loss for outliers.
Module 6 · Downhill
Walking down the loss: gradient descent with momentum, RMSProp that ignores the gradient's size, and Adam that combines them.
Module 7 · Learning
Where the gradients come from and what they achieve: backpropagation through a layer, a network that learns XOR, and LAMB for large batches.
Module 8 · Memory and attention
Networks that read a sequence: a recurrent cell and its fading echo, the gates of an LSTM, and attention over every position at once.
Module 9 · The transformer and the reward
The parts of a transformer and of an agent: positions as clocks, one encoder block, and PPO, which learns from reward without lurching.