GELU: a dip below zero
You will learn
What GELU computes, why it dips below zero, and how close its tanh shortcut comes.
GELU weighs x by the chance that a standard normal draw is below it: GELU(x) = x Phi(x). A large positive input passes, a large negative one vanishes, and in between the curve dips to about -0.17 near x = -0.75 before it rises. BERT and GPT use it in their feed-forward layers. The exact form needs erf, which the spec computes with the Abramowitz-Stegun fit, good to 1.5e-7, and it also computes the tanh shortcut: at -0.75 they give -0.16997 and -0.17004. The spec gelu_activation.t27 computes both curves and their slopes.
Try it
Find the lowest point of the curve by its slope; then compare the exact and the tanh form at -3.
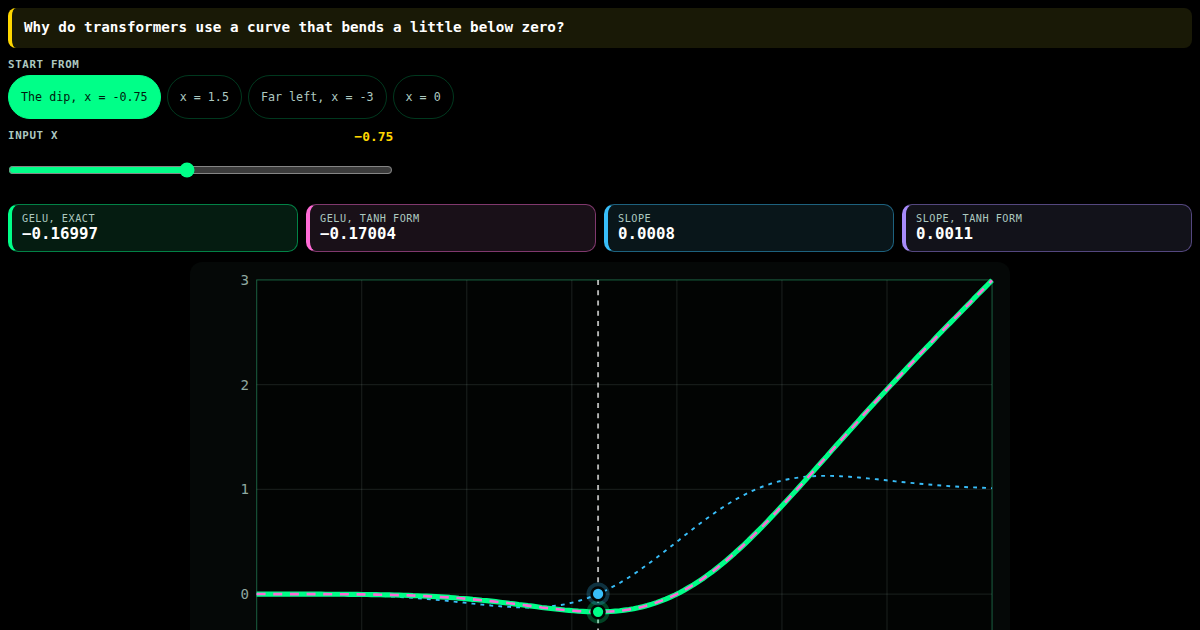
Drag along GELU: x weighed by the chance a normal draw is below it. It dips to about -0.17 before it rises, and the tanh shortcut stays within a few thousandths of the exact form.
specs/ml/activation/gelu_activation.t27
// SPDX-License-Identifier: Apache-2.0
// t27/specs/
// Based on cumulative distribution function | φ² + 1/φ² = 3 | TRINITY

// #8980: Zig has neither `@tanh` nor `@erf`, so this never compiled. erf is now
// a function of this spec (Abramowitz-Stegun 7.1.26, |error| < 1.5e-7), and the
// exact derivative divides the normal density by sqrt(2 pi), not sqrt(2) (the
// slip was invisible at x = 0, the only point the tests checked).

module Gelu;
    use base::types;
    use math::constants;

    // ═══════════════════════════════════════════════════════════
    // 1. Constants
    // ═══════════════════════════════════════════════════════════

    const SQRT_2_OVER_PI : f32 = 0.7978845608;
    const SQRT_PI_OVER_2 : f32 = 1.2533141373;
    const SQRT_2 : f32 = 1.4142135624;
    const SQRT_2_PI : f32 = 2.5066282746;

    // ═══════════════════════════════════════════════════════════
    // 2. Types
    // ═══════════════════════════════════════════════════════════

    pub const GELUConfig = struct {
        approximate : bool,
    };

    // ═══════════════════════════════════════════════════════════
    // 3. Core Functions
    // ═══════════════════════════════════════════════════════════

    // erf(x), Abramowitz-Stegun 7.1.26: max absolute error 1.5e-7
    fn erf(x: f32) -> f32 {
        if (x < 0.0) {
            return -erf(-x);
        }
        const t = 1.0 / (1.0 + 0.3275911 * x);
        const poly = t * (0.254829592 + t * (-0.284496736 + t * (1.421413741 + t * (-1.453152027 + t * 1.061405429))));
        return 1.0 - poly * exp(-x * x);
    }

    // One element. approximate: 0.5 x (1 + tanh(sqrt(2/pi) (x + 0.044715 x^3)));
    // exact: 0.5 x (1 + erf(x / sqrt(2))) = x Phi(x)
    fn gelu_one(x: f32, approximate: bool) -> f32 {
        if (approximate) {
            const inner = SQRT_2_OVER_PI * (x + 0.044715 * x * x * x);
            return 0.5 * x * (1.0 + tanh(inner));
        }
        return 0.5 * x * (1.0 + erf(x / SQRT_2));
    }

    // d/dx of gelu_one
    fn gelu_grad_one(x: f32, approximate: bool) -> f32 {
        if (approximate) {
            const inner = SQRT_2_OVER_PI * (x + 0.044715 * x * x * x);
            const tanh_val = tanh(inner);
            const sech_sq = 1.0 - tanh_val * tanh_val;
            return 0.5 * (1.0 + tanh_val) + 0.5 * x * sech_sq * SQRT_2_OVER_PI * (1.0 + 3.0 * 0.044715 * x * x);
        }
        // Phi(x) + x phi(x), phi(x) = exp(-x^2 / 2) / sqrt(2 pi)
        const cdf = 0.5 * (1.0 + erf(x / SQRT_2));
        const pdf = exp(-0.5 * x * x) / SQRT_2_PI;
        return cdf + x * pdf;
    }

    fn forward(input: []const f32, output: []f32, config: GELUConfig) -> void {
        var i : usize = 0;
        while (i < input.len) {
            output[i] = gelu_one(input[i], config.approximate);
            i = i + 1;
        }
    }

    fn backward(grad_output: []const f32, input: []const f32, grad_input: []f32, config: GELUConfig) -> void {
        var i : usize = 0;
        while (i < input.len) {
            grad_input[i] = grad_output[i] * gelu_grad_one(input[i], config.approximate);
            i = i + 1;
        }
    }

    // forward / backward over a one-element slice, for the tests
    fn forward_at(x: f32, approximate: bool) -> f32 {
        const input : [1]f32 = [x];
        var output : [1]f32 = [0.0];
        forward(&input, &output, GELUConfig{ .approximate = approximate });
        return output[0];
    }

    fn backward_at(x: f32, approximate: bool) -> f32 {
        const grad_output : [1]f32 = [1.0];
        const input : [1]f32 = [x];
        var grad_input : [1]f32 = [0.0];
        backward(&grad_output, &input, &grad_input, GELUConfig{ .approximate = approximate });
        return grad_input[0];
    }

    // ═══════════════════════════════════════════════════════════
    // TDD: Tests (from .tri behaviors)
    // ═══════════════════════════════════════════════════════════

    // The product goes through a function so the check runs, not only folds at compile time.
    fn product_of(a: f32, b: f32) -> f32 {
        return a * b;
    }

    fn config_of(approximate: bool) -> GELUConfig {
        return GELUConfig{ .approximate = approximate };
    }

    test gelu_sqrt_constants_are_reciprocals
        given product = product_of(SQRT_2_OVER_PI, SQRT_PI_OVER_2)
        then @abs(product - 1.0) < 0.0000005

    test gelu_sqrt_2_over_pi_squares_to_2_over_pi
        given squared = product_of(SQRT_2_OVER_PI, SQRT_2_OVER_PI)
        then @abs(squared - 0.63661977) < 0.0000003

    test gelu_config_records_the_approximation_choice
        given exact = config_of(false)
        when approx = config_of(true)
        then !exact.approximate and approx.approximate

    // erf(0) = 0, erf(1) = 0.8427008, erf(-1) = -erf(1)
    test gelu_erf_known_values
        given at_one = erf(1.0)
        when at_zero = erf(0.0)
        then @abs(at_zero) < 0.0000002 and @abs(at_one - 0.8427008) < 0.0000003 and erf(-1.0) == -at_one

    test gelu_forward_zero_input
        given exact = forward_at(0.0, false)
        when approx = forward_at(0.0, true)
        then exact == 0.0 and approx == 0.0

    test gelu_backward_zero_input_derivative
        given exact = backward_at(0.0, false)
        when approx = backward_at(0.0, true)
        then @abs(exact - 0.5) < 0.0000002 and approx == 0.5

    test gelu_forward_monotonic_positive_tail
        given small = forward_at(1.0, true)
        when large = forward_at(2.0, true)
        then small < large

    // With the cubic term, approximate GELU(1) = 0.8411920; exact GELU(1) = Phi(1) = 0.8413447.
    // Without it, 0.5 (1 + tanh(0.7978846)) = 0.8296438 -- so this pins the term.
    test gelu_tanh_cubic_coefficient
        given approx = forward_at(1.0, true)
        when exact = forward_at(1.0, false)
        then @abs(approx - 0.8411920) < 0.000001 and @abs(exact - 0.8413447) < 0.000001

    test gelu_backward_exact_derivative_at_zero
        given result = backward_at(0.0, false)
        then @abs(result - 0.5) < 0.0000002

    test gelu_forward_approx_derivative_at_zero
        given result = backward_at(0.0, true)
        then result == 0.5

    // The derivative at x = 1 is where the old sqrt(2) slip showed: 1.0833155 exact
    test gelu_backward_matches_finite_difference
        given exact_slope = (forward_at(1.001, false) - forward_at(0.999, false)) / 0.002
        when approx_slope = (forward_at(1.001, true) - forward_at(0.999, true)) / 0.002
        then @abs(backward_at(1.0, false) - exact_slope) < 0.002 and @abs(backward_at(1.0, true) - approx_slope) < 0.002 and @abs(backward_at(1.0, false) - 1.0833155) < 0.000002
All lessons
Module 1 · One neuron
A neuron sums its inputs and bends the sum: ReLU, the sigmoid and tanh, and where each one stops passing a gradient back.
Module 2 · New bends
The smooth curves of current models: GELU with its dip, Swish with its knob, and ELU with a floor instead of a cliff.
Module 3 · A layer
What sits around the neurons: softmax turns scores into a choice, an embedding turns a word into numbers, dropout switches units off.
Module 4 · Pictures
Reading a picture in patches: a window averaged over its patch, max pooling, and batch normalisation of features on different scales.
Module 5 · The error
How wrong a guess is, as one number: mean squared error, cross-entropy for probabilities, and the Huber loss for outliers.
Module 6 · Downhill
Walking down the loss: gradient descent with momentum, RMSProp that ignores the gradient's size, and Adam that combines them.
Module 7 · Learning
Where the gradients come from and what they achieve: backpropagation through a layer, a network that learns XOR, and LAMB for large batches.
Module 8 · Memory and attention
Networks that read a sequence: a recurrent cell and its fading echo, the gates of an LSTM, and attention over every position at once.
Module 9 · The transformer and the reward
The parts of a transformer and of an agent: positions as clocks, one encoder block, and PPO, which learns from reward without lurching.